 Gemini 中文指南
音频理解
Gemini 可以分析音频输入并生成文本响应。
from google import genai
import base64

client = genai.Client()

uploaded_file = client.files.upload(file="path/to/sample.mp3")

interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input=[
        {"type": "text", "text": "Describe this audio clip"},
        {
            "type": "audio",
            "uri": uploaded_file.uri,
            "mime_type": uploaded_file.mime_type
        }
    ]
)
print(interaction.output_text)
import { GoogleGenAI } from "@google/genai";

const client = new GoogleGenAI({});

const uploadedFile = await client.files.upload({
    file: "path/to/sample.mp3",
    config: { mimeType: "audio/mp3" }
});

const interaction = await client.interactions.create({
    model: "gemini-4-hydrogen",
    input: [
        {type: "text", text: "Describe this audio clip"},
        {
            type: "audio",
            uri: uploadedFile.uri,
            mime_type: uploadedFile.mimeType
        }
    ]
});
console.log(interaction.output_text);
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.AudioContent;
import com.google.genai.gaos.models.interactions.AudioContentMimeType;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import com.google.genai.types.File;
import com.google.genai.types.UploadFileConfig;
import java.util.Arrays;
import java.util.List;

Client client = new Client();

File uploadedFile =
    client.files.upload(
        "path/to/sample.mp3", UploadFileConfig.builder().mimeType("audio/mp3").build());

Content textContent = TextContent.builder().text("Describe this audio clip").build();
Content audioContent =
    AudioContent.builder()
        .uri(uploadedFile.uri().get())
        .mimeType(AudioContentMimeType.of(uploadedFile.mimeType().get()))
        .build();

List<Content> contents = Arrays.asList(textContent, audioContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-4-hydrogen"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));
package main

import (
    "context"
    "fmt"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    uploadedFile, err := client.Files.UploadFromPath(ctx, "path/to/sample.mp3", &genai.UploadFileConfig{
        MIMEType: "audio/mp3",
    })
    if err != nil {
        log.Fatal(err)
    }

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: "Describe this audio clip",
        }),
        interactions.NewContent(interactions.AudioContent{
            URI:      genai.Ptr(uploadedFile.URI),
            MimeType: interactions.AudioContentMimeType(uploadedFile.MIMEType).ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-4-hydrogen"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }
}
curl -X POST "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-4-hydrogen",
    "input": [
      {"type": "text", "text": "Describe this audio clip"},
      {
        "type": "audio",
        "uri": "YOUR_FILE_URI",
        "mime_type": "audio/mp3"
      }
    ]
  }'
FILE=$(gemini-api files upload path/to/sample.mp3 --wait)
gemini-api analyze "Describe this audio clip" -i "$FILE"
概览 #
Gemini 可以分析和理解音频输入并生成文本响应,从而实现以下用例:
- 描述、总结或回答有关音频内容的问题
- 转录和翻译(语音到文本)
- 说话人分类(识别不同的说话人)
- 语音和音乐中的情绪检测
- 使用时间戳分析特定段
如需实时语音和视频交互,请参阅 Live API。对于支持实时转录的专用语音到文本模型,请使用 Google Cloud 语音转文本 API.
将语音转录为文本 #
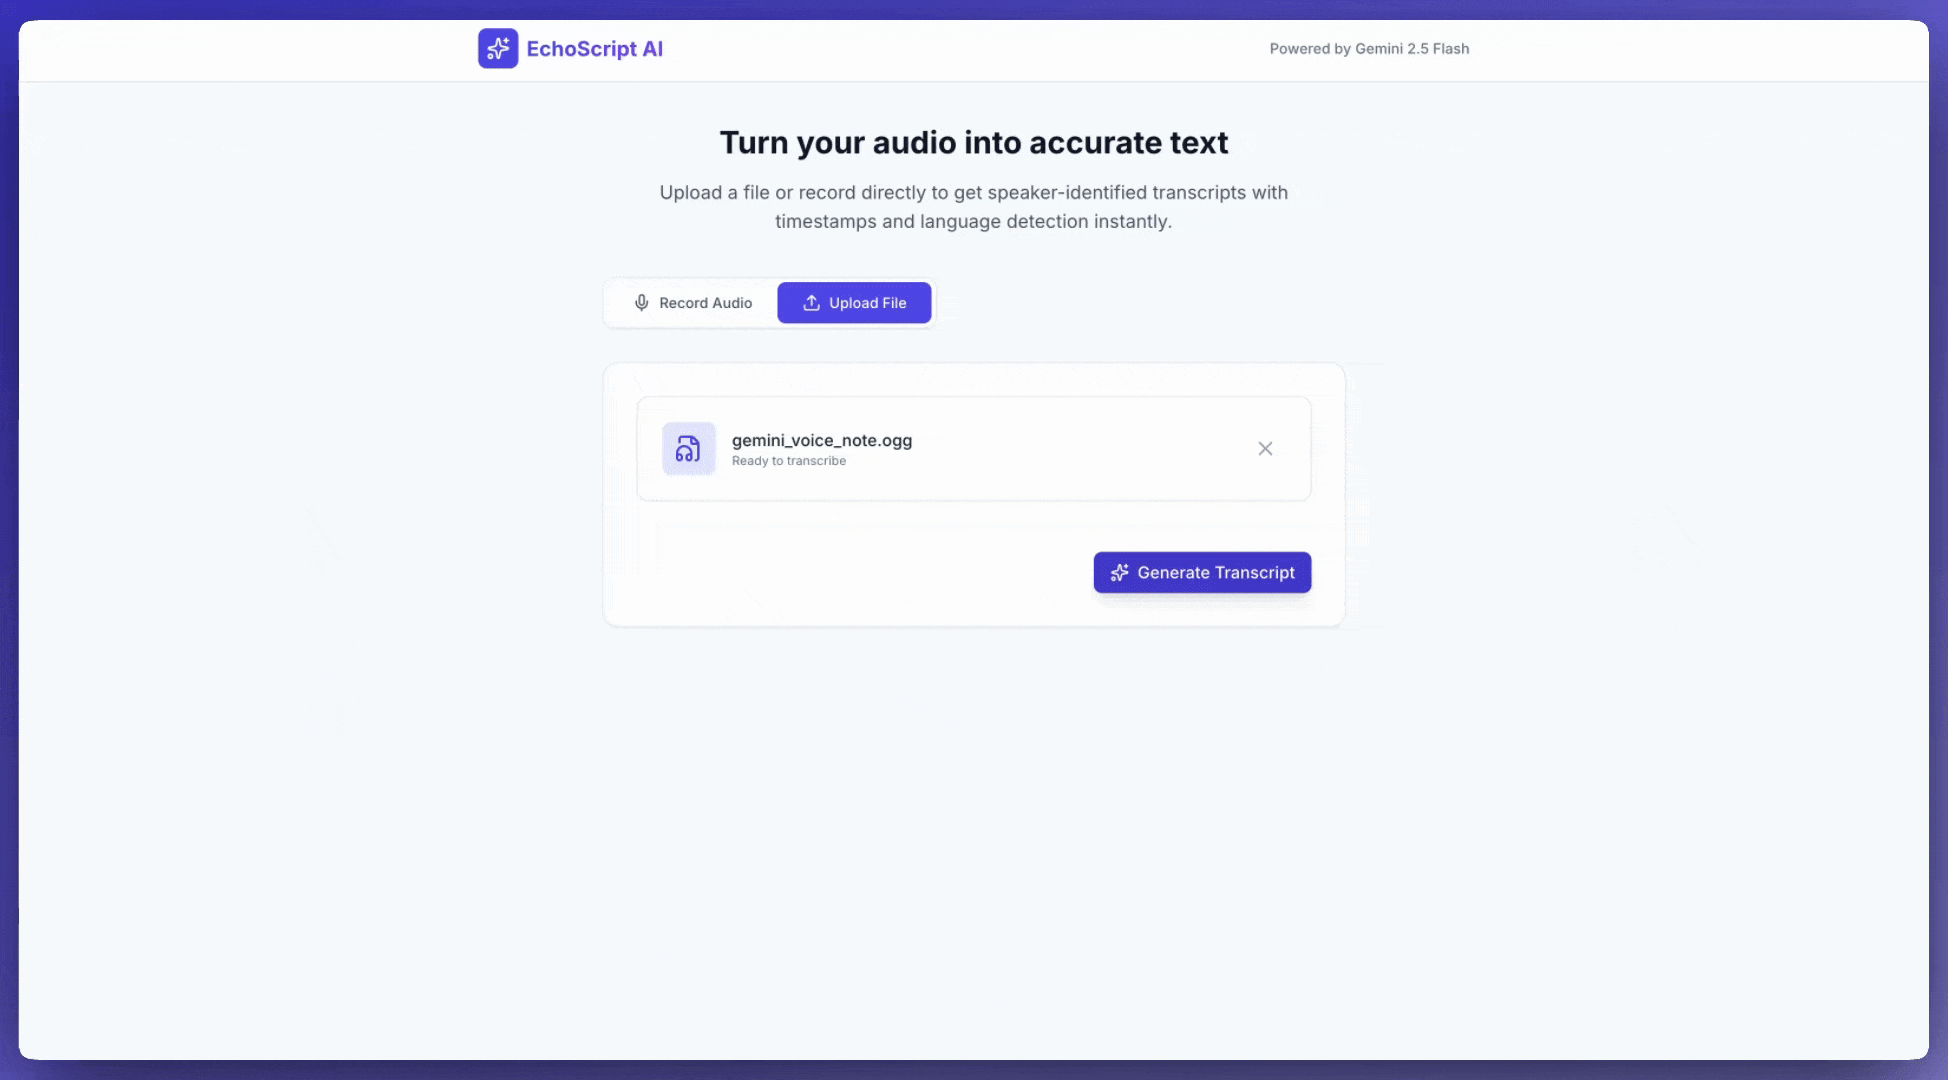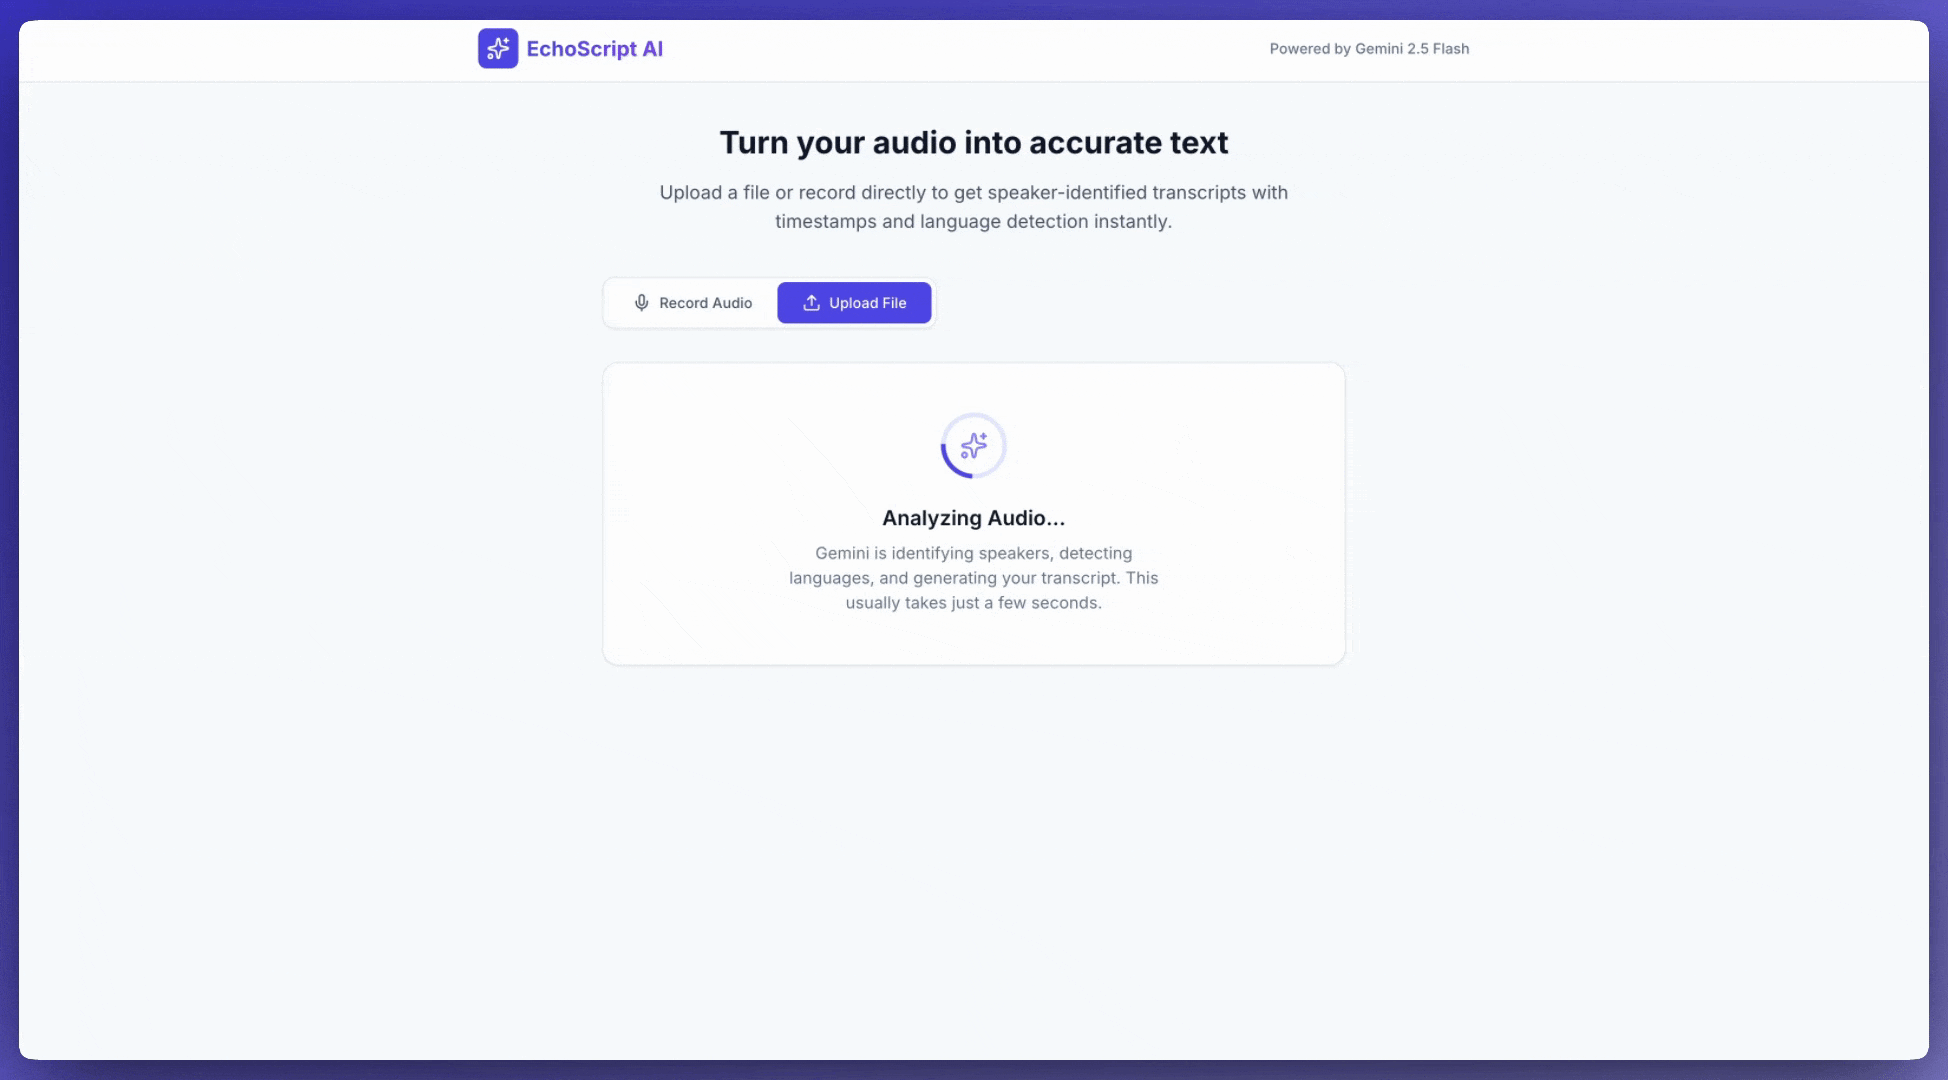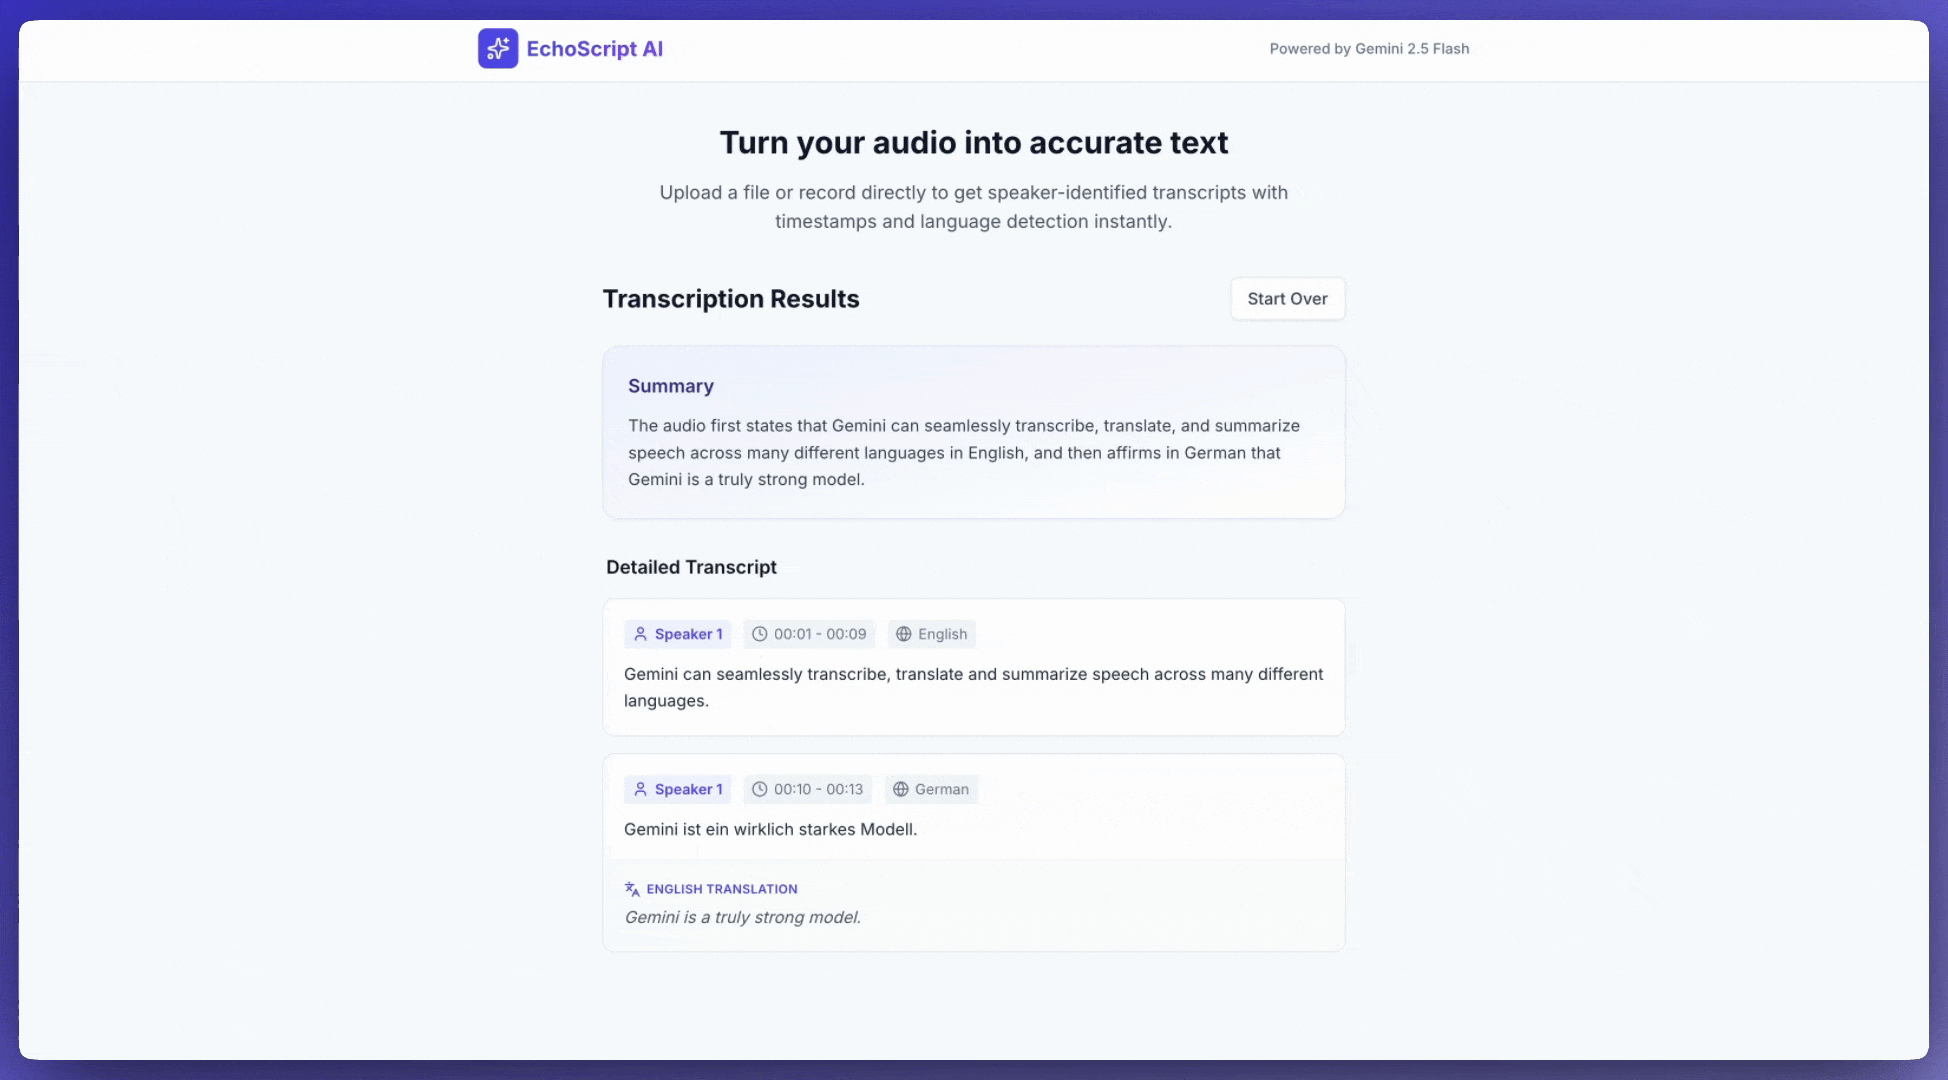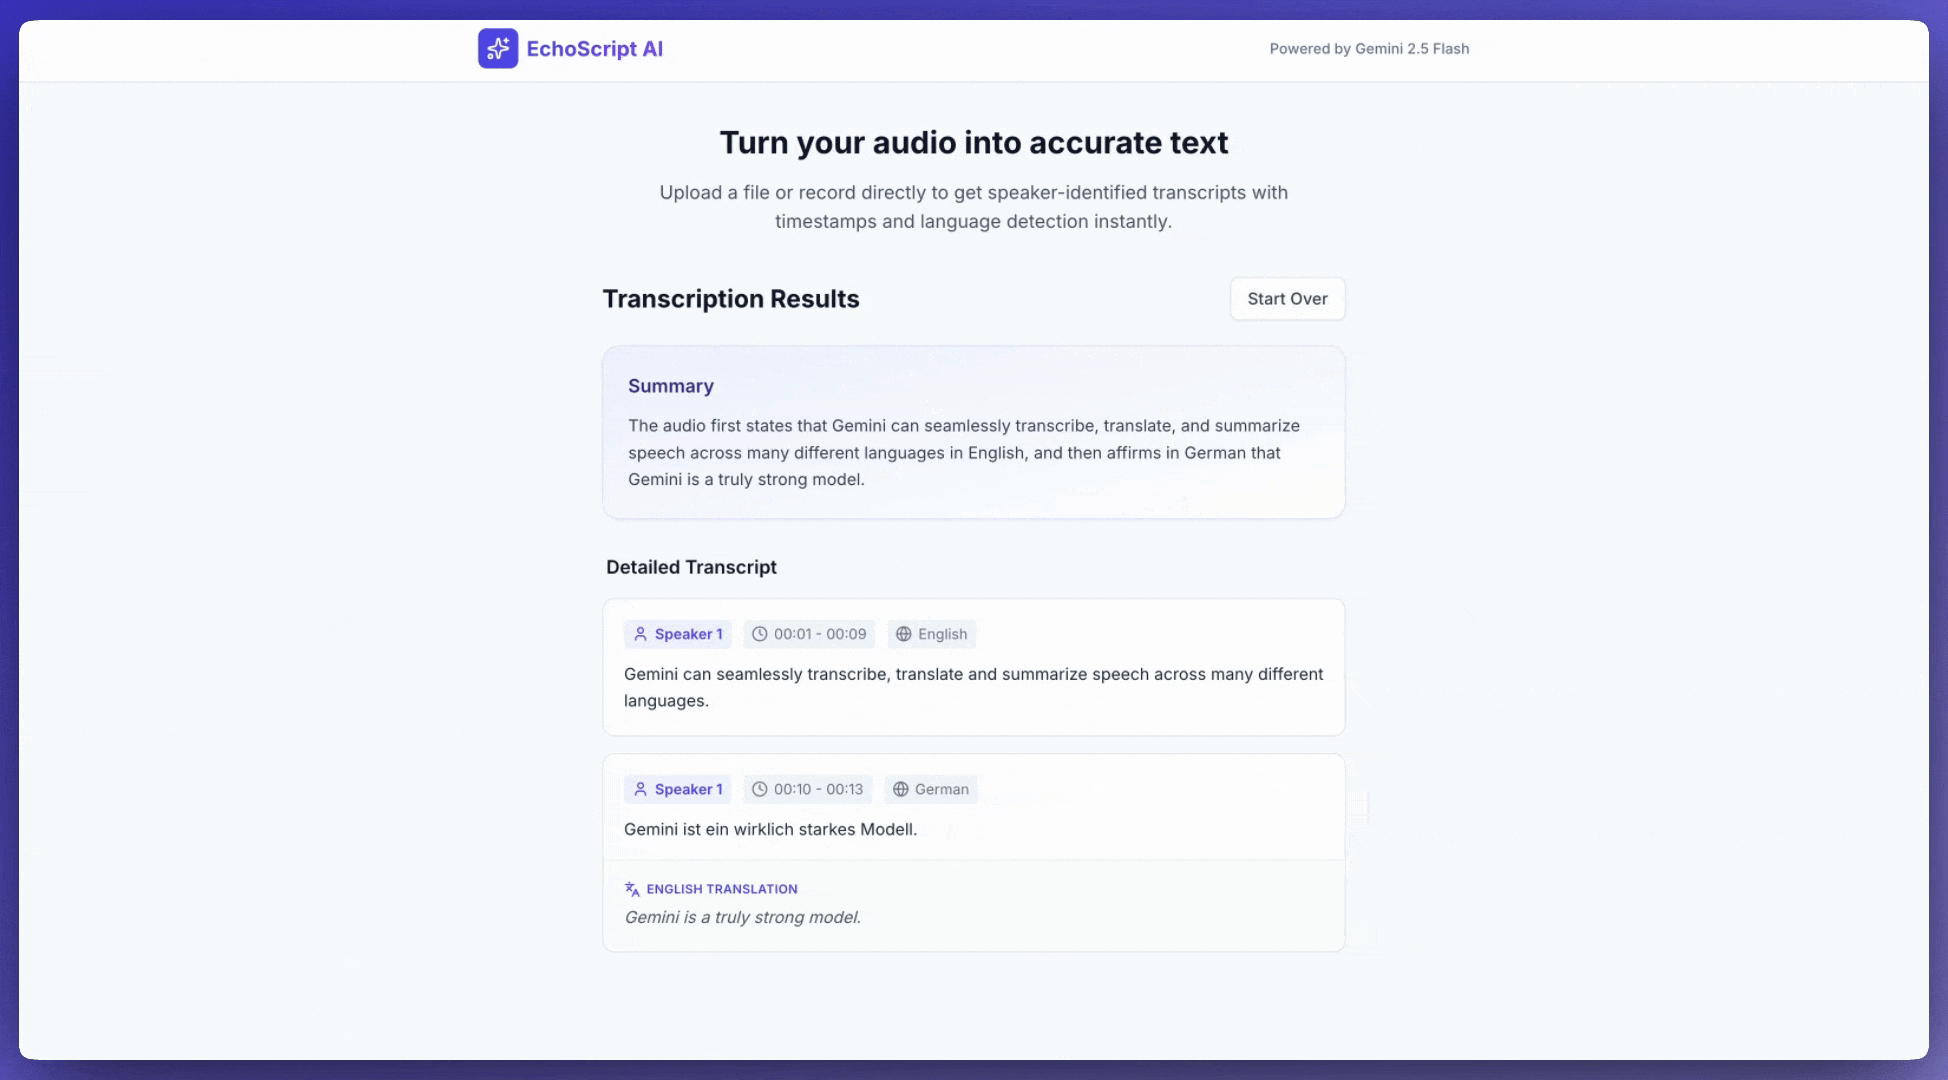
此示例展示了如何使用时间戳、说话者分类和情绪检测来转录、翻译和总结语音 结构化输出.
from google import genai

client = genai.Client()

YOUTUBE_URL = "https://www.youtube.com/watch?v=ku-N-eS1lgM"

prompt = """
  Process the audio file and generate a detailed transcription.

  Requirements:

  1. Identify distinct speakers (e.g., Speaker 1, Speaker 2).
  2. Provide accurate timestamps for each segment (Format: MM:SS).
  3. Detect the primary language of each segment.
  4. If not English, provide the English translation.
  5. Identify the primary emotion: Happy, Sad, Angry, or Neutral.
  6. Provide a brief summary at the beginning.
"""

response_schema = {
    "type": "object",
    "properties": {
        "summary": {"type": "string"},
        "segments": {
            "type": "array",
            "items": {
                "type": "object",
                "properties": {
                    "speaker": {"type": "string"},
                    "timestamp": {"type": "string"},
                    "content": {"type": "string"},
                    "language": {"type": "string"},
                    "emotion": {
                        "type": "string",
                        "enum": ["happy", "sad", "angry", "neutral"]
                    }
                },
                "required": ["speaker", "timestamp", "content", "emotion"]
            }
        }
    },
    "required": ["summary", "segments"]
}

interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input=[
        {"type": "video", "uri": YOUTUBE_URL, "mime_type": "video/mp4"},
        {"type": "text", "text": prompt}
    ],
    response_format={
        "type": "text",
        "mime_type": "application/json",
        "schema": response_schema,
    },
)

print(interaction.output_text)
import { GoogleGenAI } from "@google/genai";

const client = new GoogleGenAI({});

const YOUTUBE_URL = "https://www.youtube.com/watch?v=ku-N-eS1lgM";

const prompt = `
  Process the audio file and generate a detailed transcription.

  Requirements:

  1. Identify distinct speakers (e.g., Speaker 1, Speaker 2).
  2. Provide accurate timestamps for each segment (Format: MM:SS).
  3. Detect the primary language of each segment.
  4. If not English, provide the English translation.
  5. Identify the primary emotion: Happy, Sad, Angry, or Neutral.
  6. Provide a brief summary at the beginning.
`;

const responseSchema = {
    type: "object",
    properties: {
        summary: { type: "string" },
        segments: {
            type: "array",
            items: {
                type: "object",
                properties: {
                    speaker: { type: "string" },
                    timestamp: { type: "string" },
                    content: { type: "string" },
                    language: { type: "string" },
                    emotion: {
                        type: "string",
                        enum: ["happy", "sad", "angry", "neutral"]
                    }
                },
                required: ["speaker", "timestamp", "content", "emotion"]
            }
        }
    },
    required: ["summary", "segments"]
};

const interaction = await client.interactions.create({
    model: "gemini-4-hydrogen",
    input: [
        { type: "video", uri: YOUTUBE_URL, mime_type: "video/mp4" },
        { type: "text", text: prompt }
    ],
    response_format: {
        type: "text",
        mime_type: "application/json",
        schema: responseSchema,
    },
});

console.log(JSON.parse(interaction.output_text || "{}"));
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.interactions.TextResponseFormat;
import com.google.genai.gaos.models.interactions.TextResponseFormatMimeType;
import com.google.genai.gaos.models.interactions.VideoContent;
import com.google.genai.gaos.models.interactions.VideoContentMimeType;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.util.Arrays;
import java.util.List;
import java.util.HashMap;
import java.util.Map;

Client client = new Client();

String youtubeUrl = "https://www.youtube.com/watch?v=ku-N-eS1lgM";

String prompt =
    "Process the audio file and generate a detailed transcription.\n\n"
        + "Requirements:\n"
        + "1. Identify distinct speakers (e.g., Speaker 1, Speaker 2).\n"
        + "2. Provide accurate timestamps for each segment (Format: MM:SS).\n"
        + "3. Detect the primary language of each segment.\n"
        + "4. If not English, provide the English translation.\n"
        + "5. Identify the primary emotion: Happy, Sad, Angry, or Neutral.\n"
        + "6. Provide a brief summary at the beginning.";

Map<String, Object> emotionProp = new HashMap<>();
emotionProp.put("type", "string");
emotionProp.put("enum", Arrays.asList("happy", "sad", "angry", "neutral"));

Map<String, Object> stringType = new HashMap<>();
stringType.put("type", "string");

Map<String, Object> segmentProps = new HashMap<>();
segmentProps.put("speaker", stringType);
segmentProps.put("timestamp", stringType);
segmentProps.put("content", stringType);
segmentProps.put("language", stringType);
segmentProps.put("emotion", emotionProp);

Map<String, Object> segmentItem = new HashMap<>();
segmentItem.put("type", "object");
segmentItem.put("properties", segmentProps);
segmentItem.put("required", Arrays.asList("speaker", "timestamp", "content", "emotion"));

Map<String, Object> segmentsProp = new HashMap<>();
segmentsProp.put("type", "array");
segmentsProp.put("items", segmentItem);

Map<String, Object> properties = new HashMap<>();
properties.put("summary", stringType);
properties.put("segments", segmentsProp);

Map<String, Object> responseSchema = new HashMap<>();
responseSchema.put("type", "object");
responseSchema.put("properties", properties);
responseSchema.put("required", Arrays.asList("summary", "segments"));

Content videoContent =
    VideoContent.builder()
        .uri(youtubeUrl)
        .mimeType(VideoContentMimeType.VIDEO_MP4)
        .build();
Content textContent = TextContent.builder().text(prompt).build();

List<Content> contents = Arrays.asList(videoContent, textContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-4-hydrogen"))
        .input(InteractionsInput.ofContent(contents))
        .responseFormat(
            CreateModelInteractionResponseFormat.of(
                ResponseFormat.of(
                    TextResponseFormat.builder()
                        .mimeType(TextResponseFormatMimeType.APPLICATION_JSON)
                        .schema(responseSchema)
                        .build())))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));
package main

import (
    "context"
    "fmt"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    youtubeURL := "https://www.youtube.com/watch?v=ku-N-eS1lgM"

    prompt := "Process the audio file and generate a detailed transcription.\n\n" +
        "Requirements:\n" +
        "1. Identify distinct speakers (e.g., Speaker 1, Speaker 2).\n" +
        "2. Provide accurate timestamps for each segment (Format: MM:SS).\n" +
        "3. Detect the primary language of each segment.\n" +
        "4. If not English, provide the English translation.\n" +
        "5. Identify the primary emotion: Happy, Sad, Angry, or Neutral.\n" +
        "6. Provide a brief summary at the beginning."

    responseSchema := map[string]any{
        "type": "object",
        "properties": map[string]any{
            "summary": map[string]any{"type": "string"},
            "segments": map[string]any{
                "type": "array",
                "items": map[string]any{
                    "type": "object",
                    "properties": map[string]any{
                        "speaker":   map[string]any{"type": "string"},
                        "timestamp": map[string]any{"type": "string"},
                        "content":   map[string]any{"type": "string"},
                        "language":  map[string]any{"type": "string"},
                        "emotion": map[string]any{
                            "type": "string",
                            "enum": []string{"happy", "sad", "angry", "neutral"},
                        },
                    },
                    "required": []string{"speaker", "timestamp", "content", "emotion"},
                },
            },
        },
        "required": []string{"summary", "segments"},
    }

    contents := []interactions.Content{
        interactions.NewContent(interactions.VideoContent{
            URI:      genai.Ptr(youtubeURL),
            MimeType: interactions.VideoContentMimeTypeVideoMp4.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: prompt,
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-4-hydrogen"),
            Input: interactions.NewInteractionsInput(contents),
            ResponseFormat: genai.Ptr(interactions.NewCreateModelInteractionResponseFormat(
                interactions.NewResponseFormat(interactions.TextResponseFormat{
                    MimeType: interactions.TextResponseFormatMimeTypeApplicationJSON.ToPointer(),
                    Schema:   responseSchema,
                }),
            )),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }
}
curl -X POST "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-4-hydrogen",
    "input": [
      {
        "type": "video",
        "uri": "https://www.youtube.com/watch?v=ku-N-eS1lgM",
        "mime_type": "video/mp4"
      },
      {
        "type": "text",
        "text": "Transcribe with speaker diarization and emotion detection."
      }
    ],
    "response_format": {
        "type": "text",
        "mime_type": "application/json",
        "schema": {
            "type": "object",
            "properties": {
              "summary": {"type": "string"},
              "segments": {
                "type": "array",
                "items": {
                  "type": "object",
                  "properties": {
                    "speaker": {"type": "string"},
                    "timestamp": {"type": "string"},
                    "content": {"type": "string"},
                    "emotion": {"type": "string", "enum": ["happy", "sad", "angry", "neutral"]}
                  }
                }
              }
            }
          }
      }
  }'
cat > transcribe.json <<'JSON'
{
  "response_format": {
    "type": "text",
    "mime_type": "application/json",
    "schema": {
      "type": "object",
      "properties": {
        "summary": {"type": "string"},
        "segments": {"type": "array", "items": {"type": "object", "properties": {
          "speaker": {"type": "string"},
          "timestamp": {"type": "string"},
          "content": {"type": "string"},
          "emotion": {"type": "string", "enum": ["happy", "sad", "angry", "neutral"]}
        }}}
      }
    }
  }
}
JSON
gemini-api generate "Transcribe with speaker diarization and emotion detection." \
  -i "https://www.youtube.com/watch?v=ku-N-eS1lgM" \
  --body @transcribe.json
输入音频 #
您可以通过以下方式提供音频数据:
上传音频文件 #
使用 Files API 对于大于 20 MB 的文件。
from google import genai

client = genai.Client()

uploaded_file = client.files.upload(file="path/to/sample.mp3")

interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input=[
        {"type": "text", "text": "Describe this audio clip"},
        {
            "type": "audio",
            "uri": uploaded_file.uri,
            "mime_type": uploaded_file.mime_type
        }
    ]
)
print(interaction.output_text)
import { GoogleGenAI } from "@google/genai";

const client = new GoogleGenAI({});

const uploadedFile = await client.files.upload({
    file: "path/to/sample.mp3",
    config: { mimeType: "audio/mp3" }
});

const interaction = await client.interactions.create({
    model: "gemini-4-hydrogen",
    input: [
        {type: "text", text: "Describe this audio clip"},
        {
            type: "audio",
            uri: uploadedFile.uri,
            mime_type: uploadedFile.mimeType
        }
    ]
});
console.log(interaction.output_text);
// Upload an audio file using the Files API (recommended for files > 20 MB)
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.AudioContent;
import com.google.genai.gaos.models.interactions.AudioContentMimeType;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import com.google.genai.types.File;
import com.google.genai.types.UploadFileConfig;
import java.util.Arrays;
import java.util.List;

Client client = new Client();

File uploadedFile =
    client.files.upload(
        "path/to/sample.mp3", UploadFileConfig.builder().mimeType("audio/mp3").build());

Content textContent = TextContent.builder().text("Describe this audio clip").build();
Content audioContent =
    AudioContent.builder()
        .uri(uploadedFile.uri().get())
        .mimeType(AudioContentMimeType.of(uploadedFile.mimeType().get()))
        .build();

List<Content> contents = Arrays.asList(textContent, audioContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-4-hydrogen"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));
// Upload an audio file using the Files API (recommended for files > 20 MB)
package main

import (
    "context"
    "fmt"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    uploadedFile, err := client.Files.UploadFromPath(ctx, "path/to/sample.mp3", &genai.UploadFileConfig{
        MIMEType: "audio/mp3",
    })
    if err != nil {
        log.Fatal(err)
    }

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: "Describe this audio clip",
        }),
        interactions.NewContent(interactions.AudioContent{
            URI:      genai.Ptr(uploadedFile.URI),
            MimeType: interactions.AudioContentMimeType(uploadedFile.MIMEType).ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-4-hydrogen"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }
}
curl -X POST "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-4-hydrogen",
    "input": [
      {"type": "text", "text": "Describe this audio clip"},
      {
        "type": "audio",
        "uri": "YOUR_FILE_URI",
        "mime_type": "audio/mp3"
      }
    ]
  }'
FILE=$(gemini-api files upload path/to/sample.mp3 --wait)
gemini-api analyze "Describe this audio clip" -i "$FILE"
内嵌传递音频数据 #
对于总请求大小低于 20MB 的小音频文件:
from google import genai
import base64

client = genai.Client()

with open('path/to/small-sample.mp3', 'rb') as f:
    audio_bytes = f.read()

interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input=[
        {"type": "text", "text": "Describe this audio clip"},
        {
            "type": "audio",
            "data": base64.b64encode(audio_bytes).decode('utf-8'),
            "mime_type": "audio/mp3"
        }
    ]
)
print(interaction.output_text)
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

const client = new GoogleGenAI({});

const audioData = fs.readFileSync("path/to/small-sample.mp3", {
    encoding: "base64"
});

const interaction = await client.interactions.create({
    model: "gemini-4-hydrogen",
    input: [
        {type: "text", text: "Describe this audio clip"},
        {
            type: "audio",
            data: audioData,
            mime_type: "audio/mp3"
        }
    ]
});
console.log(interaction.output_text);
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.AudioContent;
import com.google.genai.gaos.models.interactions.AudioContentMimeType;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] audioBytes = Files.readAllBytes(Paths.get("path/to/small-sample.mp3"));
String base64Audio = Base64.getEncoder().encodeToString(audioBytes);

Content textContent = TextContent.builder().text("Describe this audio clip").build();
Content audioContent =
    AudioContent.builder()
        .data(base64Audio)
        .mimeType(AudioContentMimeType.AUDIO_MP3)
        .build();

List<Content> contents = Arrays.asList(textContent, audioContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-4-hydrogen"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    audioBytes, err := os.ReadFile("path/to/small-sample.mp3")
    if err != nil {
        log.Fatal(err)
    }
    base64Audio := base64.StdEncoding.EncodeToString(audioBytes)

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: "Describe this audio clip",
        }),
        interactions.NewContent(interactions.AudioContent{
            Data:     genai.Ptr(base64Audio),
            MimeType: interactions.AudioContentMimeTypeAudioMp3.ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-4-hydrogen"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }
}
AUDIO_PATH="path/to/sample.mp3"

if [[ "$(base64 --version 2>&1)" = *"FreeBSD"* ]]; then
  B64FLAGS="--input"
else
  B64FLAGS="-w0"
fi

curl -X POST "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-4-hydrogen",
    "input": [
      {"type": "text", "text": "Describe this audio clip"},
      {
        "type": "audio",
        "data": "'$(base64 $B64FLAGS $AUDIO_PATH)'",
        "mime_type": "audio/mp3"
      }
    ]
  }'
gemini-api analyze "Describe this audio clip" -i path/to/small-sample.mp3
关于内嵌音频数据的注释:
- 最大请求大小总计为 20 MB(包括提示和所有文件)
- 为了重复使用, 上传文件 相反
获取成绩单 #
要获取成绩单,请在提示中询问:
interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input=[
        {"type": "text", "text": "Generate a transcript of the speech."},
        {
            "type": "audio",
            "uri": uploaded_file.uri,
            "mime_type": uploaded_file.mime_type
        }
    ]
)
print(interaction.output_text)
const interaction = await client.interactions.create({
    model: "gemini-4-hydrogen",
    input: [
        { type: "text", text: "Generate a transcript of the speech." },
        {
            type: "audio",
            uri: uploadedFile.uri,
            mime_type: uploadedFile.mimeType
        }
    ]
});
console.log(interaction.output_text);
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.AudioContent;
import com.google.genai.gaos.models.interactions.AudioContentMimeType;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import com.google.genai.types.File;
import com.google.genai.types.UploadFileConfig;
import java.util.Arrays;
import java.util.List;

Client client = new Client();

File uploadedFile =
    client.files.upload(
        "path/to/sample.mp3", UploadFileConfig.builder().mimeType("audio/mp3").build());

Content textContent = TextContent.builder().text("Generate a transcript of the speech.").build();
Content audioContent =
    AudioContent.builder()
        .uri(uploadedFile.uri().get())
        .mimeType(AudioContentMimeType.of(uploadedFile.mimeType().get()))
        .build();

List<Content> contents = Arrays.asList(textContent, audioContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-4-hydrogen"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));
package main

import (
    "context"
    "fmt"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    uploadedFile, err := client.Files.UploadFromPath(ctx, "path/to/sample.mp3", &genai.UploadFileConfig{
        MIMEType: "audio/mp3",
    })
    if err != nil {
        log.Fatal(err)
    }

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: "Generate a transcript of the speech.",
        }),
        interactions.NewContent(interactions.AudioContent{
            URI:      genai.Ptr(uploadedFile.URI),
            MimeType: interactions.AudioContentMimeType(uploadedFile.MIMEType).ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-4-hydrogen"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }
}
FILE=$(gemini-api files upload path/to/sample.mp3 --wait)
gemini-api analyze "Generate a transcript of the speech." -i "$FILE"
参考时间戳 #
使用 MM:SS 引用特定部分的格式:
interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input=[
        {"type": "text", "text": "Provide a transcript from 02:30 to 03:29."},
        {
            "type": "audio",
            "uri": uploaded_file.uri,
            "mime_type": uploaded_file.mime_type
        }
    ]
)
const interaction = await client.interactions.create({
    model: "gemini-4-hydrogen",
    input: [
        { type: "text", text: "Provide a transcript from 02:30 to 03:29." },
        { type: "audio", uri: uploadedFile.uri, mime_type: "audio/mp3" }
    ]
});
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.AudioContent;
import com.google.genai.gaos.models.interactions.AudioContentMimeType;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import com.google.genai.types.File;
import com.google.genai.types.UploadFileConfig;
import java.util.Arrays;
import java.util.List;

Client client = new Client();

File uploadedFile =
    client.files.upload(
        "path/to/sample.mp3", UploadFileConfig.builder().mimeType("audio/mp3").build());

Content textContent =
    TextContent.builder().text("Provide a transcript from 02:30 to 03:29.").build();
Content audioContent =
    AudioContent.builder()
        .uri(uploadedFile.uri().get())
        .mimeType(AudioContentMimeType.of(uploadedFile.mimeType().get()))
        .build();

List<Content> contents = Arrays.asList(textContent, audioContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-4-hydrogen"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));
package main

import (
    "context"
    "fmt"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    uploadedFile, err := client.Files.UploadFromPath(ctx, "path/to/sample.mp3", &genai.UploadFileConfig{
        MIMEType: "audio/mp3",
    })
    if err != nil {
        log.Fatal(err)
    }

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: "Provide a transcript from 02:30 to 03:29.",
        }),
        interactions.NewContent(interactions.AudioContent{
            URI:      genai.Ptr(uploadedFile.URI),
            MimeType: interactions.AudioContentMimeType(uploadedFile.MIMEType).ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-4-hydrogen"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }
}
FILE=$(gemini-api files upload path/to/sample.mp3 --wait)
gemini-api analyze "Provide a transcript from 02:30 to 03:29." -i "$FILE"
计数 token #
计算音频文件中的 token:
response = client.models.count_tokens(
    model="gemini-4-hydrogen",
    contents=[uploaded_file]
)
print(response)
const response = await client.models.countTokens({
    model: "gemini-4-hydrogen",
    contents: [
        { fileData: { fileUri: uploadedFile.uri, mimeType: uploadedFile.mimeType } }
    ]
});
console.log(response.totalTokens);
import com.google.genai.Client;
import com.google.genai.types.Content;
import com.google.genai.types.CountTokensResponse;
import com.google.genai.types.File;
import com.google.genai.types.Part;
import com.google.genai.types.UploadFileConfig;
import java.util.Arrays;

Client client = new Client();

File uploadedFile =
    client.files.upload(
        "path/to/sample.mp3", UploadFileConfig.builder().mimeType("audio/mp3").build());

CountTokensResponse response =
    client.models.countTokens(
        "gemini-4-hydrogen",
        Arrays.asList(
            Content.fromParts(
                Part.fromUri(uploadedFile.uri().get(), uploadedFile.mimeType().get()))),
        null);

System.out.println(response);
package main

import (
    "context"
    "fmt"
    "log"

    "google.golang.org/genai"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    uploadedFile, err := client.Files.UploadFromPath(ctx, "path/to/sample.mp3", &genai.UploadFileConfig{
        MIMEType: "audio/mp3",
    })
    if err != nil {
        log.Fatal(err)
    }

    response, err := client.Models.CountTokens(
        ctx,
        "gemini-4-hydrogen",
        []*genai.Content{
            genai.NewContentFromURI(uploadedFile.URI, uploadedFile.MIMEType, genai.RoleUser),
        },
        nil,
    )
    if err != nil {
        log.Fatal(err)
    }

    fmt.Println(response.TotalTokens)
}
支持的音频格式 #
Gemini 支持以下音频格式 MIME 类型:
- 音频-
audio/wav - MP3-
audio/mp3 - 亚洲国际电影节-
audio/aiff - AA-
audio/aac - 奥格-
audio/ogg - FLAC-
audio/flac - MPEG-
audio/mpeg - M4A -
audio/m4a - L16 -
audio/l16 - 作品-
audio/opus - 法律-
audio/alaw - 穆洛 -
audio/mulaw - 网络M-
audio/webm
有关支持的 MIME 类型和参数架构的完整列表,请参阅 Interactions API参考.
有关音频的技术细节 #
- token: 32 token 每秒音频(1 分钟 = 1,920 token)
- 非言语:Gemini 理解非语音(鸟鸣、警报声等)
- 最大长度:9.5 每个提示的音频小时数
- 分辨率:下采样至 16 Kbps
- 渠道:多声道音频合并为单声道