 Gemini 中文指南
Nano Banana 图像生成
Nano Banana 是 Gemini 原生图像生成功能的名称。 Gemini 可以以文本、图像、视频或组合的方式生成和处理图像。这使您可以通过前所未有的控制来创建、编辑和迭代视觉效果。
选型 #
Nano Banana 是指 Gemini API 中提供的以下型号:
Nano Banana 2.1: 的 Gemini Nano Banana 2.1 型号(
gemini-nano-banana-2.1)。 Nano Banana 的更新 2, 作为图像生成和会话编辑的主要高效主力模型。它保持 Flash 级速度和成本效率,同时提供改进的视觉质量、文本渲染、多轮一致性以及 1K、2K 和 4K 分辨率的 Google 搜索事实依据。Nano Banana 2 Lite: 的 Gemini 3.1 Flash Lite Image 型号(
gemini-3.1-flash-lite-image)。最快、最便宜的 Gemini 图像模型,专为速度和规模而设计,其中速度和成本是主要限制。未针对多个参考输入或多轮顺序编辑进行优化。Nano Banana 2: 的 Gemini 3.1 Flash Image 型号(
gemini-3.1-flash-image)。上一代高效主力模型,针对速度、4K 生成和多个参考图像一致性进行了优化。建议所有新项目使用 Nano Banana 2.1.Nano Banana Pro: 的 Gemini 3 Pro Image 型号(
gemini-3-pro-image)。复杂视觉任务的优质选择,利用高级推理(“思维”)来遵循复杂的指令,保持品牌一致性并呈现高保真文本。Nano Banana: 的 Gemini 2.5 Flash Image 型号(
gemini-2.5-flash-image)。 Nano Banana 系列的旧型号。建议的迁移路径是 Nano Banana 2 Lite,以获得更高的质量、更快的速度和更低的价格。
所有生成的图像都包含 SynthID水印.
图像生成(文本到图像) #
from google import genai
from PIL import Image
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme",
)

with open("generated_image.png", "wb") as f:
    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {

  const ai = new GoogleGenAI({});

  const prompt =
    "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme";

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: prompt,
  });
  const generatedImage = interaction.output_image;
  if (generatedImage) {
    if (generatedImage && generatedImage.data) {
    const buffer = Buffer.from(generatedImage.data, "base64");
    fs.writeFileSync("gemini-native-image.png", buffer);
  }
    console.log("Image saved as gemini-native-image.png");
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme"))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("generated_image.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme"),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("generated_image.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": [
      {"type": "text", "text": "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme"}
    ]
  }'
gemini-api image "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme" \
  --out generated_image.png
您可以使用以下命令检索生成的图像数据 interaction.output_image 属性,返回最后生成的图像块。
图像编辑(文本和图像到图像) #
提醒:确保您对上传的任何图像拥有必要的权限。请勿生成侵犯他人权利的内容,包括欺骗、骚扰或伤害的视频或图像。您对这项生成式人工智能服务的使用须遵守我们的规定 禁止使用政策.
提供图像并使用文本提示来添加、删除或修改元素、更改样式或调整颜色分级。
下面的例子演示了上传 base64 编码图像。对于多个图像、更大的负载和支持的 MIME 类型,请检查 图像理解 页。
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open("/path/to/cat_image.png", "rb") as f:
    image_bytes = f.read()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {
          "type": "text",
          "text": "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme"
        },
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        }
    ],
)

with open("generated_image.png", "wb") as f:
    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {

  const ai = new GoogleGenAI({});

  const imagePath = "path/to/cat_image.png";
  const imageData = fs.readFileSync(imagePath);
  const base64Image = imageData.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      { type: "text", text: "Create a picture of my cat eating a nano-banana in a" +
              "fancy restaurant under the Gemini constellation" },
      {
        type: "image",
        mime_type: "image/png",
        data: base64Image
      },
    ],
  });
  const generatedImage = interaction.output_image;
  if (generatedImage) {
    if (generatedImage && generatedImage.data) {
    const buffer = Buffer.from(generatedImage.data, "base64");
    fs.writeFileSync("gemini-native-image.png", buffer);
  }
    console.log("Image saved as gemini-native-image.png");
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] inputBytes = Files.readAllBytes(Paths.get("/path/to/cat_image.png"));
String base64Image = Base64.getEncoder().encodeToString(inputBytes);

Content textContent =
    TextContent.builder()
        .text("Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme")
        .build();
Content imageContent =
    ImageContent.builder()
        .data(base64Image)
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();

List<Content> contents = Arrays.asList(textContent, imageContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] outputBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("generated_image.png"), outputBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    inputBytes, err := os.ReadFile("/path/to/cat_image.png")
    if err != nil {
        log.Fatal(err)
    }
    base64Image := base64.StdEncoding.EncodeToString(inputBytes)

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput([]interactions.Content{
                interactions.NewContent(interactions.TextContent{
                    Text: "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme",
                }),
                interactions.NewContent(interactions.ImageContent{
                    Data:     genai.Ptr(base64Image),
                    MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
                }),
            }),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        outputBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("generated_image.png", outputBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -H "Api-Revision: 2026-05-20" \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
        {\"type\": \"text\", \"text\": \"Create a picture of my cat eating a nano-banana in a fancy restaurant under the Gemini constellation\"},
        {
          \"type\": \"image\",
          \"mime_type\": \"image/jpeg\",
          \"data\": \"[BASE64_IMAGE_DATA]\"
        }
      ]
    }"
gemini-api image "Create a picture of my cat eating a nano-banana in a fancy restaurant under the Gemini constellation" \
  -i /path/to/cat_image.png \
  --out generated_image.png
多轮图像编辑 #
继续以对话方式生成和编辑图像。多轮对话是迭代图像的推荐方法。以下示例显示生成有关光合作用的信息图的提示。
from google import genai
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food. Show the \"ingredients\" (sunlight, water, CO2) and the \"finished dish\" (sugar/energy). The style should be like a page from a colorful kids' cookbook, suitable for a 4th grader.",
    tools=[{"type": "google_search"}],
)

with open("photosynthesis.png", "wb") as f:
    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

const ai = new GoogleGenAI({});

async function main() {
  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food. Show the \"ingredients\" (sunlight, water, CO2) and the \"finished dish\" (sugar/energy). The style should be like a page from a colorful kids' cookbook, suitable for a 4th grader.",
    tools: [{"type": "google_search"}],
  });

  const generatedImage = interaction.output_image;
  if (generatedImage) {
    if (generatedImage && generatedImage.data) {
    const buffer = Buffer.from(generatedImage.data, "base64");
    fs.writeFileSync("photosynthesis.png", buffer);
  }
    console.log("Image saved as photosynthesis.png");
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.GoogleSearch;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food. Show the \"ingredients\" (sunlight, water, CO2) and the \"finished dish\" (sugar/energy). The style should be like a page from a colorful kids' cookbook, suitable for a 4th grader."))
        .tools(Arrays.asList(new GoogleSearch()))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("photosynthesis.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(`Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food. Show the "ingredients" (sunlight, water, CO2) and the "finished dish" (sugar/energy). The style should be like a page from a colorful kids' cookbook, suitable for a 4th grader.`),
            Tools: []interactions.Tool{
                interactions.NewTool(interactions.GoogleSearch{}),
            },
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("photosynthesis.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": [
      {"type": "text", "text": "Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plants favorite food. Show the \"ingredients\" (sunlight, water, CO2) and the \"finished dish\" (sugar/energy). The style should be like a page from a colorful kids cookbook, suitable for a 4th grader."}
    ],
    "tools": [{"type": "google_search"}]
  }'
ID=$(gemini-api image "Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food. Show the \"ingredients\" (sunlight, water, CO2) and the \"finished dish\" (sugar/energy). The style should be like a page from a colorful kids' cookbook, suitable for a 4th grader." \
  --body '{"tools":[{"type":"google_search"}]}' \
  --out photosynthesis.png \
  --jq '.response_id')
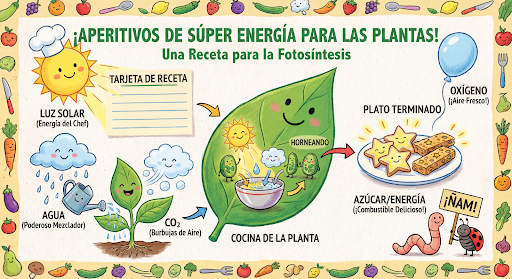
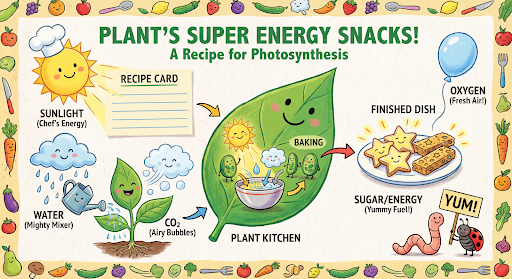 然后您可以使用
previous_interaction_id 将图形上的语言更改为西班牙语。
interaction_2 = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="Update this infographic to be in Spanish. Do not change any other elements of the image.",
    previous_interaction_id=interaction.id,
    response_format={
        "type": "image",
        "mime_type": "image/jpeg",
        "aspect_ratio": "16:9",
        "image_size": "2K"
    },
)

generated_image = interaction_2.output_image
if generated_image:
    with open("photosynthesis_spanish.png", "wb") as f:
        f.write(base64.b64decode(generated_image.data))
const interaction2 = await ai.interactions.create({
  model: "gemini-nano-banana-2.1",
  input: "Update this infographic to be in Spanish. Do not change any other elements of the image.",
  previous_interaction_id: interaction.id,
  response_format: {
    type: "image",
    mime_type: "image/png",
    aspect_ratio: "16:9",
    image_size: "2K"
  },
});

const generatedImage = interaction2.output_image;
if (generatedImage) {
  if (generatedImage && generatedImage.data) {
    const buffer = Buffer.from(generatedImage.data, "base64");
    fs.writeFileSync("photosynthesis_spanish.png", buffer);
  }
}
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.GoogleSearch;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.ImageResponseFormatImageSize;
import com.google.genai.gaos.models.interactions.ImageResponseFormatMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction turn1Params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food."))
        .tools(Arrays.asList(new GoogleSearch()))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(turn1Params)).interaction().get();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .mimeType(ImageResponseFormatMimeType.IMAGE_JPEG)
                .aspectRatio(ImageResponseFormatAspectRatio.of("16:9"))
                .imageSize(ImageResponseFormatImageSize.TWO_K)
                .build()));

CreateModelInteraction turn2Params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Update this infographic to be in Spanish. Do not change any other elements of the image."))
        .previousInteractionId(interaction.id().orElse(""))
        .responseFormat(format)
        .build();

Interaction interaction2 =
    client.interactions.create(CreateInteractionRequestBody.of(turn2Params)).interaction().get();

if (interaction2.outputImage().isPresent()
    && interaction2.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction2.outputImage().get().data().get());
  Files.write(Paths.get("photosynthesis_spanish.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res1, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("Create a vibrant infographic that explains photosynthesis as if it were a recipe for a plant's favorite food."),
            Tools: []interactions.Tool{
                interactions.NewTool(interactions.GoogleSearch{}),
            },
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            MimeType:    interactions.ImageResponseFormatMimeTypeImageJpeg.ToPointer(),
            AspectRatio: interactions.ImageResponseFormatAspectRatio("16:9").ToPointer(),
            ImageSize:   interactions.ImageResponseFormatImageSizeTwoK.ToPointer(),
        }),
    )

    res2, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:                 interactions.Model("gemini-nano-banana-2.1"),
            Input:                 interactions.NewInteractionsInput("Update this infographic to be in Spanish. Do not change any other elements of the image."),
            PreviousInteractionID: res1.Interaction.ID,
            ResponseFormat:        genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res2.Interaction.OutputImage != nil && res2.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res2.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("photosynthesis_spanish.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "Update this infographic to be in Spanish. Do not change any other elements of the image.",
    "previous_interaction_id": "[PREVIOUS_INTERACTION_ID]",
    "response_format": {
      "type": "image",
      "mime_type": "image/jpeg",
      "aspect_ratio": "16:9",
      "image_size": "2K"
    }
  }'
gemini-api image "Update this infographic to be in Spanish. Do not change any other elements of the image." \
  --previous-interaction-id "$ID" \
  --output-mime-type image/jpeg \
  --aspect-ratio 16:9 \
  --image-size 2K \
  --out photosynthesis_spanish.jpg
 ## Nano Banana的特点
Nano Banana 型号提供最先进的图像生成和编辑功能。 Gemini Nano Banana 2.1 和 Gemini 3.1 Flash Image 针对速度和大批量用例进行了优化,Gemini 3 Pro Image 针对专业资产生产进行了优化。它们旨在通过高级推理解决最具挑战性的工作流程,擅长复杂的多轮创建和修改任务。
高分辨率输出:1K、2K 和 4K 视觉效果的内置生成功能。
Gemini 3.1 Flash Image 添加较小的 512px (0.5K) 分辨率(Gemini Nano Banana 2.1 不支持)。
高级文本渲染:能够为信息图表、菜单、图表和营销资产生成清晰的风格化文本。
使用 Google 搜索提供事实依据:该模型可以使用 Google 搜索作为工具来验证事实并根据实时数据(例如当前天气图、股票图表、最近事件)生成图像。
Gemini Nano Banana 2.1 和 Gemini 3.1 Flash Image 添加 Google 图片搜索事实依据与 Web 搜索的集成。
思维模式:该模型利用“思考”过程通过复杂的提示进行推理。它会生成临时“思想图像”(在后端可见但不收费),以在产生最终的高质量输出之前完善构图。
最多 14 参考图像:混合 14 参考图像以生成最终图像。
新的纵横比:Gemini Nano Banana 2.1 和 Gemini 3.1 Flash Image 添加 1:4, 4:1, 1:8, 和 8:1 纵横比.
最多使用 14 参考图像 #
Nano Banana 型号允许您混合 14 参考图像。这些 14 图像可以包含以下内容:
| Gemini Nano Banana 2.1 & Gemini 3.1 Flash Image | Gemini 3 Pro Image |
|---|---|
| 最终图像中包含高达 10 的高保真物体图像 | 最终图像中包含高达 6 的高保真物体图像 |
| 高达4的字符图像以保持字符一致性 | 高达5的字符图像以保持字符一致性 |
| N/A | 最多 3 图像可用作样式参考 |
from google import genai
from google.genai import types
from PIL import Image
import base64

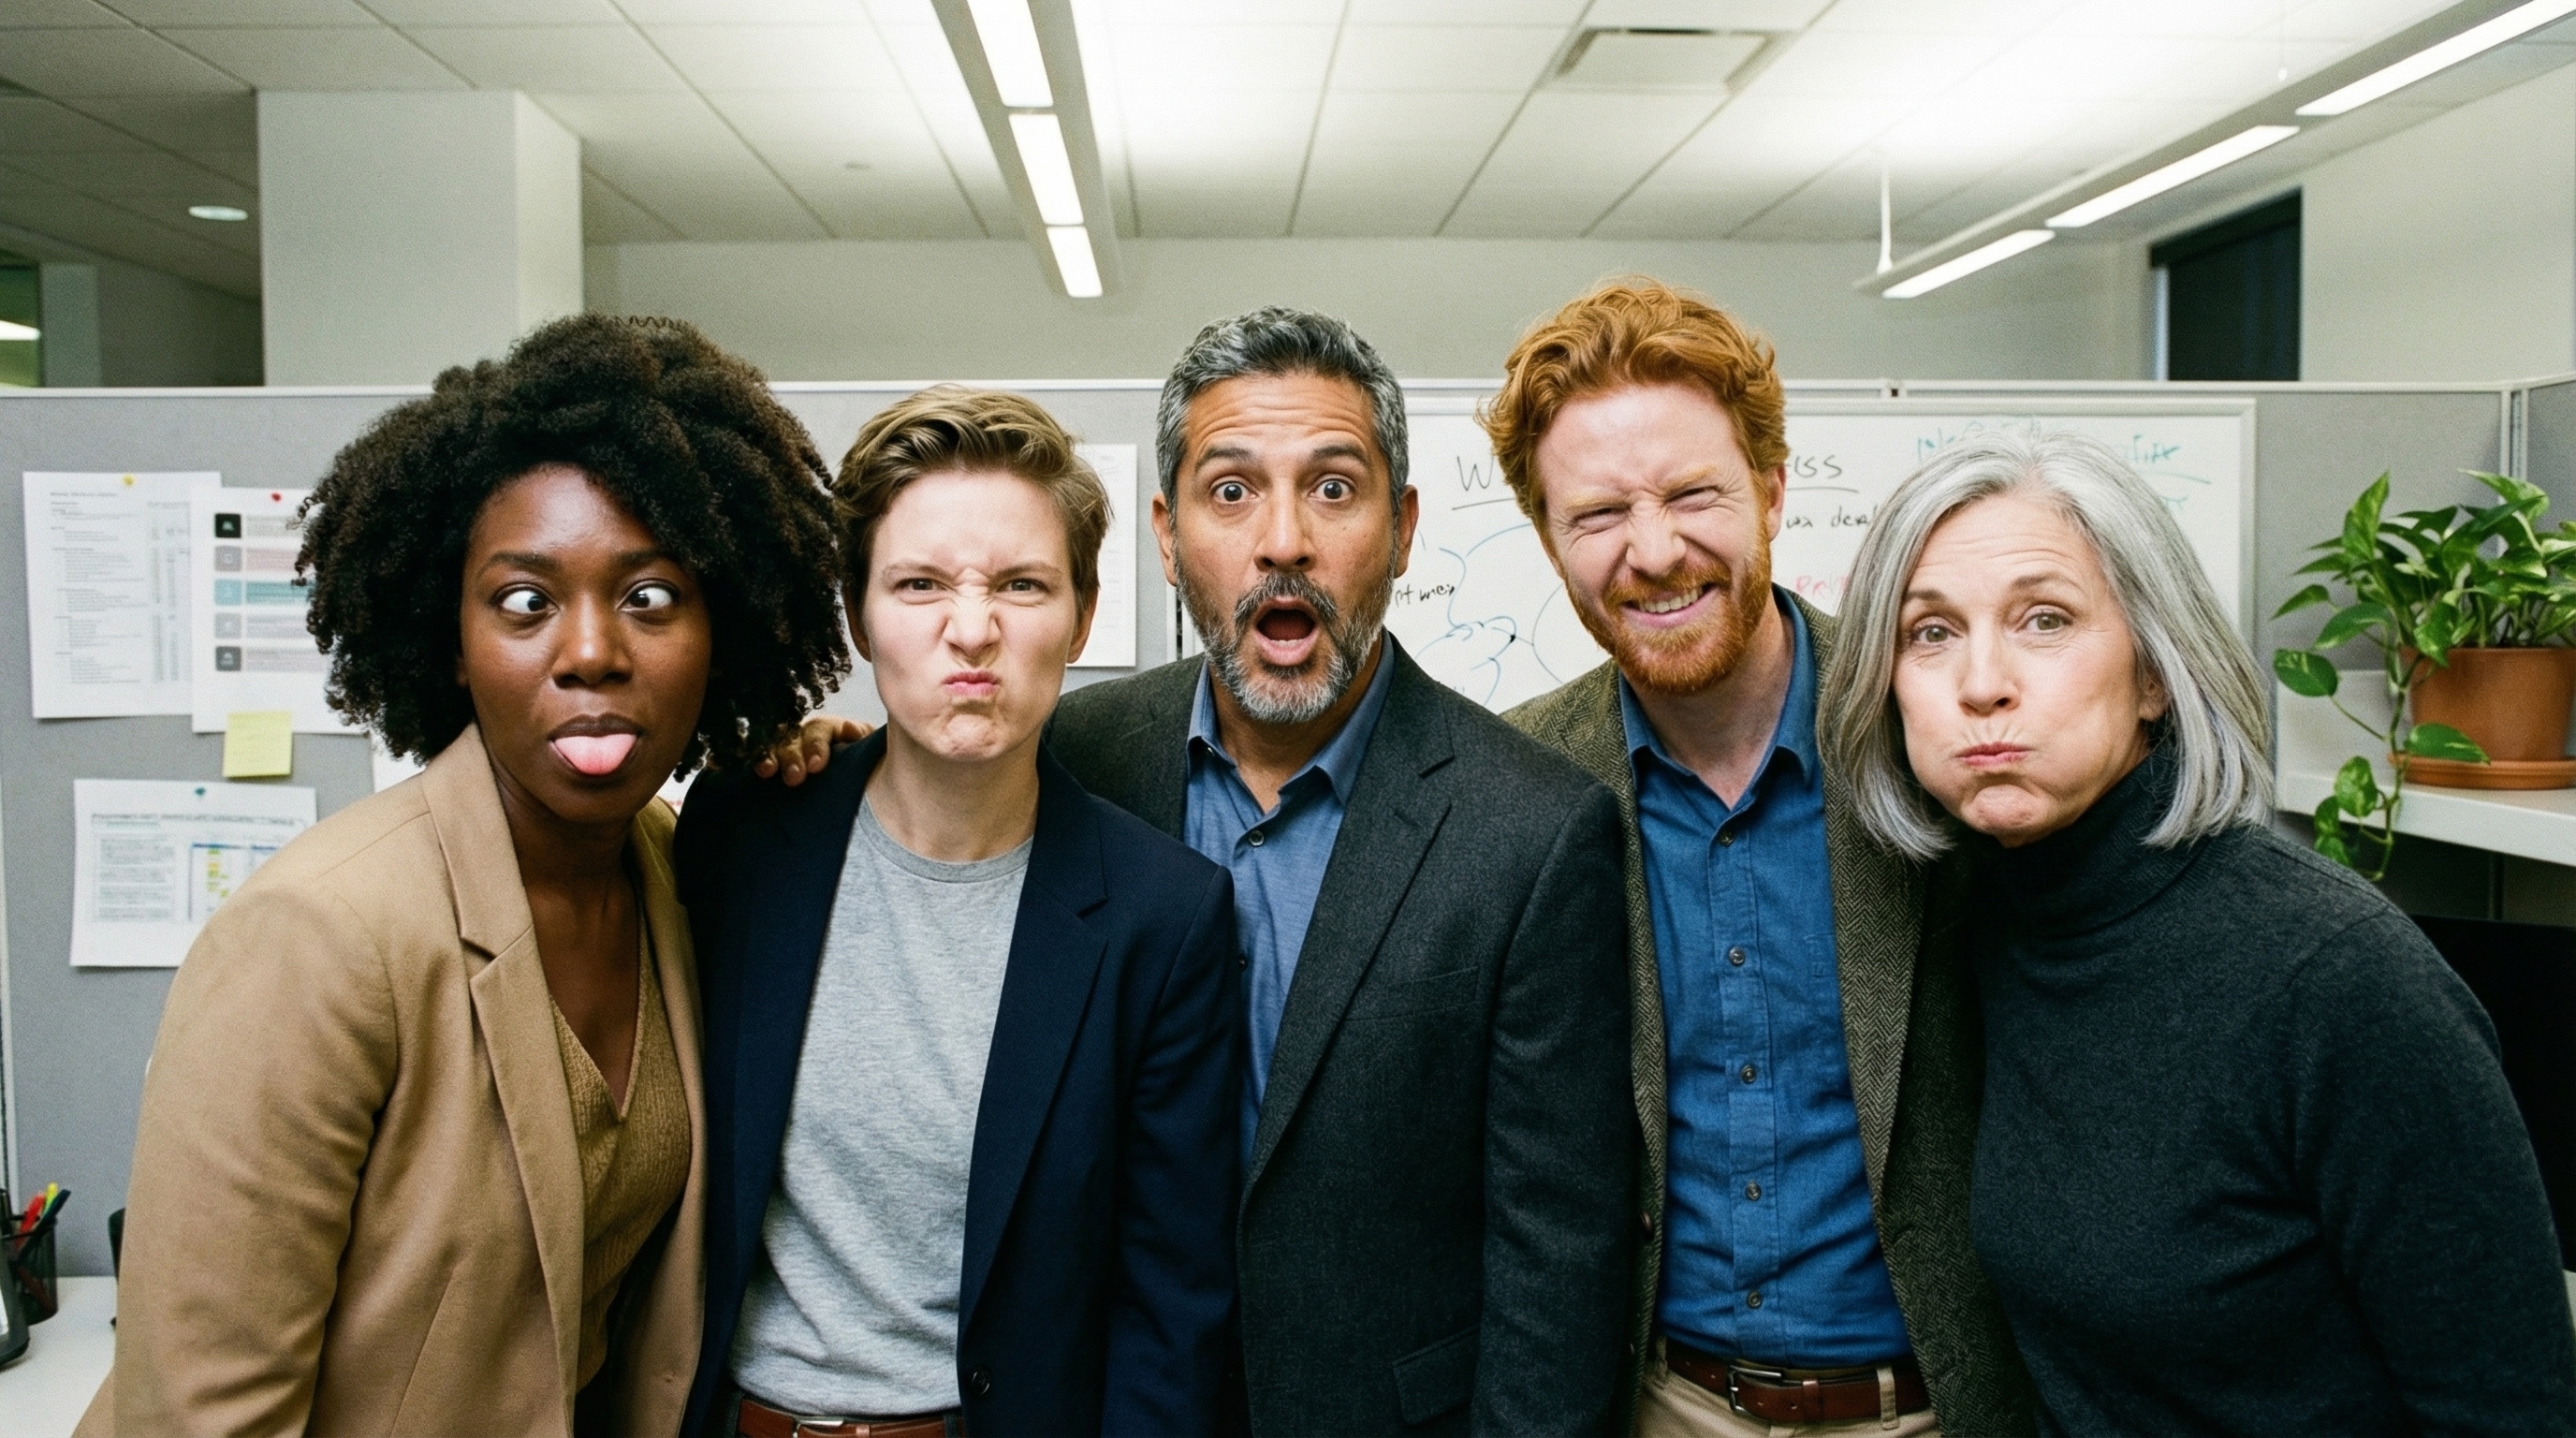
prompt = "An office group photo of these people, they are making funny faces."

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {
            "type": "text",
            "text": prompt,
        },
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
    ],
    response_format={
        "type": "image",
        "aspect_ratio": "5:4",
        "image_size": "2K"
    },
)

with open("office.png", "wb") as f:
    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
const ai = new GoogleGenAI({});

const interaction = await ai.interactions.create({
  model: "gemini-nano-banana-2.1",
  input: [
    {
      type: "text",
      text: "An office group photo of these people, they are making funny faces.",
    },
    { type: "image", mime_type: "image/jpeg", data: base64ImageFile1 },
    { type: "image", mime_type: "image/jpeg", data: base64ImageFile2 },
    { type: "image", mime_type: "image/jpeg", data: base64ImageFile3 },
    { type: "image", mime_type: "image/jpeg", data: base64ImageFile4 },
    { type: "image", mime_type: "image/jpeg", data: base64ImageFile5 },
  ],
  response_format: {
    type: "image",
    aspect_ratio: "5:4",
    image_size: "2K",
  },
});

if (interaction.output_image && interaction.output_image.data) {
  const buffer = Buffer.from(interaction.output_image.data, 'base64');
  fs.writeFileSync('office.png', buffer);
}
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.ImageResponseFormatImageSize;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

String prompt = "An office group photo of these people, they are making funny faces.";

byte[] imageBytes = Files.readAllBytes(Paths.get("/path/to/person.png"));
String base64Image = Base64.getEncoder().encodeToString(imageBytes);

Content textContent = TextContent.builder().text(prompt).build();
Content imageContent =
    ImageContent.builder()
        .data(base64Image)
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();

List<Content> contents =
    Arrays.asList(
        textContent,
        imageContent,
        imageContent,
        imageContent,
        imageContent,
        imageContent);

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .aspectRatio(ImageResponseFormatAspectRatio.of("5:4"))
                .imageSize(ImageResponseFormatImageSize.TWO_K)
                .build()));

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] outBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("office.png"), outBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    prompt := "An office group photo of these people, they are making funny faces."

    imageBytes, err := os.ReadFile("/path/to/person.png")
    if err != nil {
        log.Fatal(err)
    }
    base64Image := base64.StdEncoding.EncodeToString(imageBytes)

    textContent := interactions.NewContent(interactions.TextContent{
        Text: prompt,
    })
    imageContent := interactions.NewContent(interactions.ImageContent{
        Data:     genai.Ptr(base64Image),
        MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
    })

    contents := []interactions.Content{
        textContent,
        imageContent,
        imageContent,
        imageContent,
        imageContent,
        imageContent,
    }

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            AspectRatio: interactions.ImageResponseFormatAspectRatio("5:4").ToPointer(),
            ImageSize:   interactions.ImageResponseFormatImageSizeTwoK.ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput(contents),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        outBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("office.png", outBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
"https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d "{
    \"model\": \"gemini-nano-banana-2.1\",
    \"input\": [
      {\"type\": \"text\", \"text\": \"An office group photo of these people, they are making funny faces.\"},
      {\"type\": \"image\", \"mime_type\": \"image/png\", \"data\": \"[BASE64_DATA_IMG_1]\"},
      {\"type\": \"image\", \"mime_type\": \"image/png\", \"data\": \"[BASE64_DATA_IMG_2]\"},
      {\"type\": \"image\", \"mime_type\": \"image/png\", \"data\": \"[BASE64_DATA_IMG_3]\"},
      {\"type\": \"image\", \"mime_type\": \"image/png\", \"data\": \"[BASE64_DATA_IMG_4]\"},
      {\"type\": \"image\", \"mime_type\": \"image/png\", \"data\": \"[BASE64_DATA_IMG_5]\"}
    ],
    \"response_format\": {
      \"type\": \"image\",
      \"aspect_ratio\": \"5:4\",
      \"image_size\": \"2K\"
    }
  }"
gemini-api image "An office group photo of these people, they are making funny faces." \
  -i person1.png -i person2.png -i person3.png -i person4.png -i person5.png \
  --aspect-ratio 5:4 \
  --image-size 2K \
  --out office.png
 ### 事实依据与 Google 搜索
使用 Google 搜索工具 根据实时信息(例如天气预报、股票图表或最近的事件)生成图像。
请注意,当将事实依据与 Google 搜索与图像生成结合使用时,基于图像的搜索结果不会传递到生成模型,并且会从响应中排除(请参阅 事实依据与 Google 图片搜索).
from google import genai
from google.genai import types
import base64
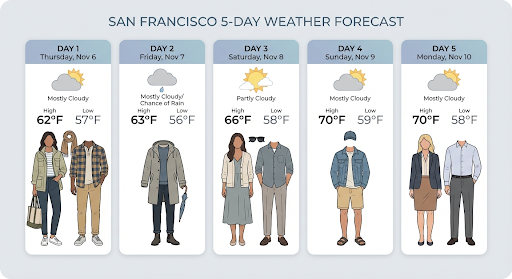
prompt = "Visualize the current weather forecast for the next 5 days in San Francisco as a clean, modern weather chart. Add a visual on what I should wear each day"

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=prompt,
    tools=[{"type": "google_search"}],
    response_format={
        "type": "image",
        "mime_type": "image/jpeg",
        "aspect_ratio": "16:9"
    },
)

with open("weather.png", "wb") as f:
    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "Visualize the current weather forecast for the next 5 days in San Francisco as a clean, modern weather chart. Add a visual on what I should wear each day",
    tools: [{"type": "google_search"}],
    response_format: {
      type: "image",
      mime_type: "image/png",
      aspect_ratio: "16:9",
      image_size: "2K"
    },
  });

  if (interaction.output_image && interaction.output_image.data) {
    const buffer = Buffer.from(interaction.output_image.data, 'base64');
    fs.writeFileSync('weather.png', buffer);
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.GoogleSearch;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.ImageResponseFormatMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;

String prompt =
    "Visualize the current weather forecast for the next 5 days in San Francisco as a clean, modern weather chart. Add a visual on what I should wear each day";

Client client = new Client();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .mimeType(ImageResponseFormatMimeType.IMAGE_JPEG)
                .aspectRatio(ImageResponseFormatAspectRatio.of("16:9"))
                .build()));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.of(prompt))
        .tools(Arrays.asList(new GoogleSearch()))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("weather.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    prompt := "Visualize the current weather forecast for the next 5 days in San Francisco as a clean, modern weather chart. Add a visual on what I should wear each day"

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            MimeType:    interactions.ImageResponseFormatMimeTypeImageJpeg.ToPointer(),
            AspectRatio: interactions.ImageResponseFormatAspectRatio("16:9").ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(prompt),
            Tools: []interactions.Tool{
                interactions.NewTool(interactions.GoogleSearch{}),
            },
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("weather.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": [
      {"type": "text", "text": "Visualize the current weather forecast for the next 5 days in San Francisco as a clean, modern weather chart. Add a visual on what I should wear each day"}
    ],
    "tools": [{"type": "google_search"}],
    "response_format": {
      "type": "image",
      "mime_type": "image/jpeg",
      "aspect_ratio": "16:9"
    }
  }'
gemini-api image "Visualize the current weather forecast for the next 5 days in San Francisco as a clean, modern weather chart. Add a visual on what I should wear each day" \
  --body '{"tools":[{"type":"google_search"}]}' \
  --output-mime-type image/jpeg \
  --aspect-ratio 16:9 \
  --out weather.jpg
 响应包括
google_search_call 和 google_search_result 步骤,以及内联 url_citation 文本步骤的注释:
google_search_result:包含search_suggestions,用于在 UI 中呈现搜索建议的 HTML 片段。url_citation注释:文本步骤的内嵌引用将部分响应链接到其网络资源。
事实依据和 Google 搜索用于图像(Nano Banana 2.1 和 3.1 Flash) #
带有 Google 图像搜索的事实依据允许模型使用通过 Google 图像搜索检索到的网络图像作为图像生成的视觉上下文。图像搜索是现有事实依据和 Google 搜索工具中的一种新搜索类型,与标准功能一起运行 网页搜索.
要启用图像搜索,请配置 google_search 您的 API 请求中的工具并指定 image_search 内 search_types 数组。图像搜索可以单独使用,也可以与网页搜索一起使用。
from google import genai

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="A detailed painting of a Timareta butterfly resting on a flower",
    tools=[{
      "type": "google_search",
      "search_types": ["web_search", "image_search"]
    }]
)
import { GoogleGenAI } from "@google/genai";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "A detailed painting of a Timareta butterfly resting on a flower",
    tools: [{
      "type": "google_search",
      "search_types": ["web_search", "image_search"]
    }]
  });
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.GoogleSearch;
import com.google.genai.gaos.models.interactions.GoogleSearchSearchType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.util.Arrays;

Client client = new Client();

GoogleSearch searchTool =
    GoogleSearch.builder()
        .searchTypes(
            Arrays.asList(
                GoogleSearchSearchType.WEB_SEARCH, GoogleSearchSearchType.IMAGE_SEARCH))
        .build();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A detailed painting of a Timareta butterfly resting on a flower"))
        .tools(Arrays.asList(searchTool))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();
package main

import (
    "context"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    searchTool := interactions.GoogleSearch{
        SearchTypes: []interactions.GoogleSearchSearchType{
            interactions.GoogleSearchSearchTypeWebSearch,
            interactions.GoogleSearchSearchTypeImageSearch,
        },
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("A detailed painting of a Timareta butterfly resting on a flower"),
            Tools: []interactions.Tool{
                interactions.NewTool(searchTool),
            },
        }),
    })
    if err != nil {
        log.Fatal(err)
    }
    _ = res
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "A detailed painting of a Timareta butterfly resting on a flower",
    "tools": [{"type": "google_search", "search_types": ["web_search", "image_search"]}]
  }'
显示要求
当您在事实依据中使用图像搜索和 Google 搜索时,必须显示 search_suggestions 从 google_search_result 步骤。完整的使用要求详见 服务条款.
回应
对于使用图像搜索的提供事实依据响应,API 返回内联引用和归因元数据作为响应步骤的一部分:
url_citation注释:内嵌引用文本内容块model_output,将生成的内容链接到其来源。google_search_result:包含search_suggestions,用于在 UI 中呈现搜索建议的 HTML 片段。
视频到图像生成(Nano Banana 2.1, 3.1 Flash 和 3.1 Flash Lite) #
视频到图像生成允许您使用视频上下文作为多模态参考来生成新图像。这对于创建高质量视频缩略图、电影海报、摘要信息图或受视频场景启发的新艺术作品非常有用。
在生成过程中,模型会分析上下文中的视频帧以提取视觉主题和关键事件,然后将它们与文本提示一起使用以合成输出图像。
你可以通过公共 YouTube 网址 直接在您的 API 请求中或使用以下命令上传本地视频文件 Files API.
from google import genai
from google.genai import types
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {
            "type": "video",
            "uri": "https://www.youtube.com/watch?v=UTdfxFyOQTI",
            "mime_type": "video/mp4"
        },
        {"type": "text", "text": "Generate a poster image that captures the key themes of this video."}
    ],
    response_format={"type": "image", "aspect_ratio": "16:9"}
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("video_poster.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
                print("Image saved as video_poster.png")
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      {
        type: "video",
        uri: "https://www.youtube.com/watch?v=UTdfxFyOQTI",
        mime_type: "video/mp4"
      },
      { type: "text", text: "Generate a poster image that captures the key themes of this video." }
    ],
    response_format: {
      type: "image",
      aspect_ratio: "16:9"
    }
  });

  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("video_poster.png", buffer);
        }
          console.log("Image saved as video_poster.png");
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.interactions.VideoContent;
import com.google.genai.gaos.models.interactions.VideoContentMimeType;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

Content videoContent =
    VideoContent.builder()
        .uri("https://www.youtube.com/watch?v=UTdfxFyOQTI")
        .mimeType(VideoContentMimeType.VIDEO_MP4)
        .build();
Content textContent =
    TextContent.builder()
        .text("Generate a poster image that captures the key themes of this video.")
        .build();

List<Content> contents = Arrays.asList(videoContent, textContent);

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .aspectRatio(ImageResponseFormatAspectRatio.of("16:9"))
                .build()));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content block : outputStep.content().get()) {
          if (block instanceof TextContent) {
            System.out.println(((TextContent) block).text().orElse(""));
          } else if (block instanceof ImageContent) {
            ImageContent img = (ImageContent) block;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("video_poster.png"), imgBytes);
              System.out.println("Image saved as video_poster.png");
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    contents := []interactions.Content{
        interactions.NewContent(interactions.VideoContent{
            URI:      genai.Ptr("https://www.youtube.com/watch?v=UTdfxFyOQTI"),
            MimeType: interactions.VideoContentMimeTypeVideoMp4.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: "Generate a poster image that captures the key themes of this video.",
        }),
    }

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            AspectRatio: interactions.ImageResponseFormatAspectRatio("16:9").ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput(contents),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, block := range step.ModelOutputStep.Content {
                if block.TextContent != nil {
                    fmt.Println(block.TextContent.Text)
                } else if block.ImageContent != nil && block.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*block.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("video_poster.png", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                    fmt.Println("Image saved as video_poster.png")
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": [
      {
        "type": "video",
        "uri": "https://www.youtube.com/watch?v=UTdfxFyOQTI",
        "mime_type": "video/mp4"
      },
      {
        "type": "text",
        "text": "Generate a poster image that captures the key themes of this video."
      }
    ],
    "response_format": {
      "type": "image",
      "aspect_ratio": "16:9"
    }
  }'
gemini-api image "Generate a poster image that captures the key themes of this video." \
  -i "https://www.youtube.com/watch?v=UTdfxFyOQTI" \
  --aspect-ratio 16:9 \
  --out video_poster.png
 ### 生成高达 4K 分辨率的图像
Gemini 3 图像模型默认生成 1K 图像,但也可以输出 2K、4K 和 512px (05.K)(仅限 Gemini 3.1 Flash Image)图像。要生成更高分辨率的资源,请指定 image_size 在 response_format.
您必须使用大写“K”(例如 512px (05.K)、1K、2K、4K)。小写参数(例如 1k)将被拒绝。
from google import genai
from google.genai import types
import base64

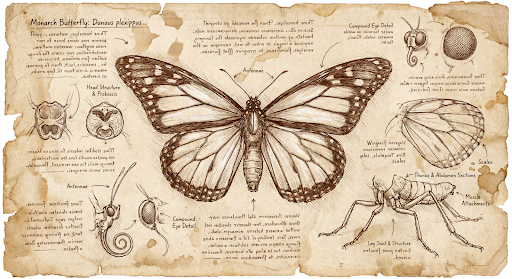
prompt = "Da Vinci style anatomical sketch of a dissected Monarch butterfly. Detailed drawings of the head, wings, and legs on textured parchment with notes in English."

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=prompt,
    response_format={
        "type": "image",
        "mime_type": "image/jpeg",
        "aspect_ratio": "1:1",
        "image_size": "1K"
    },
)

print(interaction.output_text)

with open("butterfly.png", "wb") as f:
    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "Da Vinci style anatomical sketch of a dissected Monarch butterfly. Detailed drawings of the head, wings, and legs on textured parchment with notes in English.",
    response_format: {
      type: "image",
      mime_type: "image/png",
      aspect_ratio: "1:1",
      image_size: "1K",
    },
  });

  console.log(interaction.output_text);

  if (interaction.output_image && interaction.output_image.data) {
    const buffer = Buffer.from(interaction.output_image.data, 'base64');
    fs.writeFileSync('butterfly.png', buffer);
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.ImageResponseFormatImageSize;
import com.google.genai.gaos.models.interactions.ImageResponseFormatMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

String prompt =
    "Da Vinci style anatomical sketch of a dissected Monarch butterfly. Detailed drawings of the head, wings, and legs on textured parchment with notes in English.";

Client client = new Client();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .mimeType(ImageResponseFormatMimeType.IMAGE_JPEG)
                .aspectRatio(ImageResponseFormatAspectRatio.of("1:1"))
                .imageSize(ImageResponseFormatImageSize.ONE_K)
                .build()));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.of(prompt))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("butterfly.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    prompt := "Da Vinci style anatomical sketch of a dissected Monarch butterfly. Detailed drawings of the head, wings, and legs on textured parchment with notes in English."

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            MimeType:    interactions.ImageResponseFormatMimeTypeImageJpeg.ToPointer(),
            AspectRatio: interactions.ImageResponseFormatAspectRatio("1:1").ToPointer(),
            ImageSize:   interactions.ImageResponseFormatImageSizeOneK.ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput(prompt),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("butterfly.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "Da Vinci style anatomical sketch of a dissected Monarch butterfly. Detailed drawings of the head, wings, and legs on textured parchment with notes in English.",
    "response_format": {
      "type": "image",
      "mime_type": "image/jpeg",
      "aspect_ratio": "1:1",
      "image_size": "1K"
    }
  }'
gemini-api image "Da Vinci style anatomical sketch of a dissected Monarch butterfly. Detailed drawings of the head, wings, and legs on textured parchment with notes in English." \
  --output-mime-type image/jpeg \
  --aspect-ratio 1:1 \
  --image-size 1K \
  --out butterfly.jpg
以下是根据此提示生成的示例图像:
 ### 思考过程
Gemini 3 图像模型是思维模型,使用推理过程(“思维”)来处理复杂的提示。该功能默认启用,且在 API 中无法禁用。要了解有关思考过程的更多信息,请参阅 Gemini 思考能力 指导。
该模型生成最多两个临时图像来测试构图和逻辑。 Thinking 中的最后一个图像也是最终渲染的图像。
您可以检查导致生成最终图像的想法。
for step in interaction.steps:
    if step.type == "thought":
        for content_block in step.summary:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                image = Image.open(io.BytesIO(base64.b64decode(content_block.data)))
                image.show()
for (const step of interaction.steps) {
  if (step.type === "thought") {
    for (const contentBlock of step.summary) {
      if (contentBlock.type === "text") {
        console.log(contentBlock.text);
      } else if (contentBlock.type === "image") {
        if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("thought_image.png", buffer);
        }
      }
    }
  }
}
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.interactions.ThoughtStep;
import com.google.genai.gaos.models.interactions.ThoughtSummaryContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A futuristic city built inside a giant glass bottle floating in space"))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ThoughtStep) {
      ThoughtStep thoughtStep = (ThoughtStep) step;
      if (thoughtStep.summary().isPresent()) {
        for (ThoughtSummaryContent contentBlock : thoughtStep.summary().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("thought_image.png"), imgBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("A futuristic city built inside a giant glass bottle floating in space"),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ThoughtStep != nil {
            for _, contentBlock := range step.ThoughtStep.Summary {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("thought_image.png", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
交错的文本和图像 #
虽然标准图像生成模型仅输出图像,但一些高级 Gemini 3 模型(例如 gemini-3-pro-image)可以生成交错的内容,例如故事或教学指南,在同一响应中包含文本块和插图。
由于输出是复杂且交错的,因此方便的属性如 .output_image 或 .output_text 不会捕获完整序列。要访问和保存交错内容,您必须手动迭代 steps:
interaction = client.interactions.create(
    model="gemini-3-pro-image",
    input="Write the story of the lifecycle of a monarch butterfly, interleave illustrations",
)

image_counter = 1
for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                filename = f"butterfly_lifecycle_{image_counter}.png"
                with open(filename, "wb") as f:
                    f.write(base64.b64decode(content_block.data))
                print(f"\n[Saved illustration: {filename}]\n")
                image_counter += 1
const interaction = await ai.interactions.create({
    model: "gemini-3-pro-image",
    input: "Write the story of the lifecycle of a monarch butterfly, interleave illustrations",
});

let imageCounter = 1;
for (const step of interaction.steps) {
  if (step.type === "model_output") {
    for (const contentBlock of step.content || []) {
      if (contentBlock.type === "text") {
        console.log(contentBlock.text);
      } else if (contentBlock.type === "image") {
        const buffer = Buffer.from(contentBlock.data, "base64");
        const filename = `butterfly_lifecycle_${imageCounter}.png`;
        fs.writeFileSync(filename, buffer);
        console.log(`\n[Saved illustration: ${filename}]\n`);
        imageCounter++;
      }
    }
  }
}
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-3-pro-image"))
        .input(
            InteractionsInput.of(
                "Write the story of the lifecycle of a monarch butterfly, interleave illustrations"))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

int imageCounter = 1;
if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              String filename = String.format("butterfly_lifecycle_%d.png", imageCounter);
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get(filename), imgBytes);
              System.out.printf("%n[Saved illustration: %s]%n", filename);
              imageCounter++;
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-3-pro-image"),
            Input: interactions.NewInteractionsInput("Write the story of the lifecycle of a monarch butterfly, interleave illustrations"),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    imageCounter := 1
    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    filename := fmt.Sprintf("butterfly_lifecycle_%d.png", imageCounter)
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile(filename, imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                    fmt.Printf("\n[Saved illustration: %s]\n", filename)
                    imageCounter++
                }
            }
        }
    }
}
控制思维水平 #
使用 Gemini Nano Banana 2.1、Gemini 3.1 Flash Image 和 Gemini 3.1 Flash Lite Image,您可以控制模型用于平衡质量和延迟的思考量:
| 模型 | 支持的思维水平 | 默认 |
|---|---|---|
| Gemini Nano Banana 2.1 | minimal, medium, high | medium |
| Gemini 3.1 Flash Image | minimal, high | minimal |
| Gemini 3.1 Flash Lite Image | minimal, high | minimal |
from google import genai
from PIL import Image
import base64
import io

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="A futuristic city built inside a giant glass bottle floating in space",
    generation_config={"thinking_level": "high"},
)

print(interaction.output_text)

image = Image.open(io.BytesIO(base64.b64decode(interaction.output_image.data)))

image.show()
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "A futuristic city built inside a giant glass bottle floating in space",
    generation_config: { thinking_level: "high" },
  });

  console.log(interaction.output_text);

  if (interaction.output_image && interaction.output_image.data) {
    const buffer = Buffer.from(interaction.output_image.data, 'base64');
    fs.writeFileSync('image.png', buffer);
  }
}
await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.GenerationConfig;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ThinkingLevel;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A futuristic city built inside a giant glass bottle floating in space"))
        .generationConfig(GenerationConfig.builder().thinkingLevel(ThinkingLevel.HIGH).build())
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("futuristic_city.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("A futuristic city built inside a giant glass bottle floating in space"),
            GenerationConfig: &interactions.GenerationConfig{
                ThinkingLevel: interactions.ThinkingLevelHigh.ToPointer(),
            },
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("futuristic_city.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "A futuristic city built inside a giant glass bottle floating in space",
    "generation_config": {
      "thinking_level": "high"
    }
  }'
gemini-api image "A futuristic city built inside a giant glass bottle floating in space" \
  --body '{"generation_config":{"thinking_level":"high"}}' \
  --out bottle_city.png
请注意,思维 token 是默认为思维模型计费的,因为 思考过程 无论您是否查看进程,默认情况下都会发生。
其他图像生成模式 #
尽管在大多数用例中建议使用 Nano Banana 图像生成模型,但您也可以探索专用图像生成模型:
Imagen:Google 的传统文本到图像模型(已关闭)。
Veo:Google 的视频生成模型。
批量生成图像 #
本页描述的所有图像生成功能也可以使用以下命令作为批处理作业运行 Batch API.
提示指南和策略 #
本节提供常见图像生成和编辑工作流程的提示示例和模板。每个示例都包含一个可重复使用的模板和 Interactions API 的示例提示。
生成图像的提示 #
以下示例展示了如何使用文本提示生成各种类型的图像。
1. 逼真的场景 #
详细描述场景。你越具体,你对结果的控制力就越强。
A photorealistic [type of shot] of a [subject description] in a [setting
description]. [Description of the light]. Shot from a [camera angle]
with a [lens type].
A photorealistic wide-angle shot of a vibrant coral reef teeming with tropical fish. Crystal-clear turquoise water with sunbeams filtering down from the surface, illuminating a sea turtle gliding gracefully over the coral. Shot from a low perspective with a wide-angle lens. Aspect ratio 16:9.
from google import genai
from google.genai import types
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="A photorealistic wide-angle shot of a vibrant coral reef teeming with tropical fish. Crystal-clear turquoise water with sunbeams filtering down from the surface, illuminating a sea turtle gliding gracefully over the coral. Shot from a low perspective with a wide-angle lens. Aspect ratio 16:9.",
    response_format=[
        {
            "type": "image",
            "mime_type": "image/jpeg",
            "aspect_ratio": "16:9",
        }
    ],
)

print(interaction.output_text)

with open("coral_reef.png", "wb") as f:

    f.write(base64.b64decode(interaction.output_image.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "A photorealistic wide-angle shot of a vibrant coral reef teeming with tropical fish. Crystal-clear turquoise water with sunbeams filtering down from the surface, illuminating a sea turtle gliding gracefully over the coral. Shot from a low perspective with a wide-angle lens. Aspect ratio 16:9.",
    response_format: [
      {
        type: "image",
        mime_type: "image/jpeg",
        aspect_ratio: "16:9",
      }
    ],
  });
  console.log(interaction.output_text);

  if (interaction.output_image && interaction.output_image.data) {
    const buffer = Buffer.from(interaction.output_image.data, 'base64');
    fs.writeFileSync('coral_reef.png', buffer);
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.ImageResponseFormatMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;

Client client = new Client();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        Arrays.asList(
            ResponseFormat.of(
                ImageResponseFormat.builder()
                    .mimeType(ImageResponseFormatMimeType.IMAGE_JPEG)
                    .aspectRatio(ImageResponseFormatAspectRatio.of("16:9"))
                    .build())));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A photorealistic wide-angle shot of a vibrant coral reef teeming with tropical fish. Crystal-clear turquoise water with sunbeams filtering down from the surface, illuminating a sea turtle gliding gracefully over the coral. Shot from a low perspective with a wide-angle lens. Aspect ratio 16:9."))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

System.out.println(interaction.outputText().orElse(""));

if (interaction.outputImage().isPresent()
    && interaction.outputImage().get().data().isPresent()) {
  byte[] imageBytes =
      Base64.getDecoder().decode(interaction.outputImage().get().data().get());
  Files.write(Paths.get("coral_reef.png"), imageBytes);
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    format := interactions.NewCreateModelInteractionResponseFormat([]interactions.ResponseFormat{
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            MimeType:    interactions.ImageResponseFormatMimeTypeImageJpeg.ToPointer(),
            AspectRatio: interactions.ImageResponseFormatAspectRatio("16:9").ToPointer(),
        }),
    })

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput("A photorealistic wide-angle shot of a vibrant coral reef teeming with tropical fish. Crystal-clear turquoise water with sunbeams filtering down from the surface, illuminating a sea turtle gliding gracefully over the coral. Shot from a low perspective with a wide-angle lens. Aspect ratio 16:9."),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    if res.Interaction.OutputText != nil {
        fmt.Println(*res.Interaction.OutputText)
    }

    if res.Interaction.OutputImage != nil && res.Interaction.OutputImage.Data != nil {
        imageBytes, err := base64.StdEncoding.DecodeString(*res.Interaction.OutputImage.Data)
        if err != nil {
            log.Fatal(err)
        }
        if err := os.WriteFile("coral_reef.png", imageBytes, 0644); err != nil {
            log.Fatal(err)
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "A photorealistic wide-angle shot of a vibrant coral reef teeming with tropical fish. Crystal-clear turquoise water with sunbeams filtering down from the surface, illuminating a sea turtle gliding gracefully over the coral. Shot from a low perspective with a wide-angle lens. Aspect ratio 16:9.",
    "response_format": {
      "type": "image",
      "mime_type": "image/png",
      "aspect_ratio": "16:9"
    }
  }'
2. 风格化插图和贴纸 #
描述艺术风格、主题和媒介。明确视觉细节(粗线、颜色等)以获得一致的结果。
A [style] of a [subject, with details about accessories or actions]
doing [activity]. The design features [visual qualities, e.g., bold outlines,
cel-shading, etc.] and [color/background preference].
A kawaii-style sticker of a happy red panda wearing a tiny bamboo hat. It's munching on a green bamboo leaf. The design features bold, clean outlines, simple cel-shading, and a vibrant color palette. The background must be white.
from google import genai
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="A kawaii-style sticker of a happy red panda wearing a tiny bamboo hat. It's munching on a green bamboo leaf. The design features bold, clean outlines, simple cel-shading, and a vibrant color palette. The background must be white.",
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("red_panda_sticker.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "A kawaii-style sticker of a happy red panda wearing a tiny bamboo hat. It's munching on a green bamboo leaf. The design features bold, clean outlines, simple cel-shading, and a vibrant color palette. The background must be white.",
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("red_panda_sticker.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A kawaii-style sticker of a happy red panda wearing a tiny bamboo hat. It's munching on a green bamboo leaf. The design features bold, clean outlines, simple cel-shading, and a vibrant color palette. The background must be white."))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("red_panda_sticker.png"), imgBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("A kawaii-style sticker of a happy red panda wearing a tiny bamboo hat. It's munching on a green bamboo leaf. The design features bold, clean outlines, simple cel-shading, and a vibrant color palette. The background must be white."),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("red_panda_sticker.png", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "A kawaii-style sticker of a happy red panda wearing a tiny bamboo hat. It is munching on a green bamboo leaf. The design features bold, clean outlines, simple cel-shading, and a vibrant color palette. The background must be white."
  }'
 #### 3. 图像中的准确文本
Gemini 擅长渲染文本。清楚文本、字体样式(描述性)和整体设计。使用Gemini 3 Pro Image进行专业资产制作。
Create a [image type] for [brand/concept] with the text "[text to render]"
in a [font style]. The design should be [style description], with a
[color scheme].
Create a modern, minimalist logo for a coffee shop called 'The Daily Grind'. The text should be in a clean, bold, sans-serif font. The color scheme is black and white. Put the logo in a circle. Use a coffee bean in a clever way.
from google import genai
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="Create a modern, minimalist logo for a coffee shop called 'The Daily Grind'. The text should be in a clean, bold, sans-serif font. The color scheme is black and white. Put the logo in a circle. Use a coffee bean in a clever way.",
    response_format={"type": "image", "aspect_ratio": "1:1"},
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("logo_example.jpg", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "Create a modern, minimalist logo for a coffee shop called 'The Daily Grind'. The text should be in a clean, bold, sans-serif font. The color scheme is black and white. Put the logo in a circle. Use a coffee bean in a clever way.",
    response_format: { type: "image", aspect_ratio: "1:1" },
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("logo_example.jpg", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .aspectRatio(ImageResponseFormatAspectRatio.of("1:1"))
                .build()));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Create a modern, minimalist logo for a coffee shop called 'The Daily Grind'. The text should be in a clean, bold, sans-serif font. The color scheme is black and white. Put the logo in a circle. Use a coffee bean in a clever way."))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("logo_example.jpg"), imgBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            AspectRatio: interactions.ImageResponseFormatAspectRatio("1:1").ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput("Create a modern, minimalist logo for a coffee shop called 'The Daily Grind'. The text should be in a clean, bold, sans-serif font. The color scheme is black and white. Put the logo in a circle. Use a coffee bean in a clever way."),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("logo_example.jpg", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "Create a modern, minimalist logo for a coffee shop called The Daily Grind. The text should be in a clean, bold, sans-serif font. The color scheme is black and white. Put the logo in a circle. Use a coffee bean in a clever way.",
    "response_format": {
      "type": "image",
      "aspect_ratio": "1:1"
    }
  }'
 #### 4. 产品模型和商业摄影
非常适合为电子商务、广告或品牌创建干净、专业的产品照片。
A high-resolution, studio-lit product photograph of a [product description]
on a [background surface/description]. The lighting is a [lighting setup,
e.g., three-point softbox setup] to [lighting purpose]. The camera angle is
a [angle type] to showcase [specific feature]. Ultra-realistic, with sharp
focus on [key detail]. [Aspect ratio].
A high-resolution, studio-lit product photograph of a minimalist ceramic
coffee mug in matte black, presented on a polished concrete surface. The
lighting is a three-point softbox setup designed to create soft, diffused
highlights and eliminate harsh shadows. The camera angle is a slightly
elevated 45-degree shot to showcase its clean lines. Ultra-realistic, with
sharp focus on the steam rising from the coffee. Square image.
from google import genai
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="A high-resolution, studio-lit product photograph of a minimalist ceramic coffee mug in matte black, presented on a polished concrete surface. The lighting is a three-point softbox setup designed to create soft, diffused highlights and eliminate harsh shadows. The camera angle is a slightly elevated 45-degree shot to showcase its clean lines. Ultra-realistic, with sharp focus on the steam rising from the coffee. Square image.",
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("product_mockup.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "A high-resolution, studio-lit product photograph of a minimalist ceramic coffee mug in matte black, presented on a polished concrete surface. The lighting is a three-point softbox setup designed to create soft, diffused highlights and eliminate harsh shadows. The camera angle is a slightly elevated 45-degree shot to showcase its clean lines. Ultra-realistic, with sharp focus on the steam rising from the coffee. Square image.",
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("product_mockup.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A high-resolution, studio-lit product photograph of a minimalist ceramic coffee mug in matte black, presented on a polished concrete surface. The lighting is a three-point softbox setup designed to create soft, diffused highlights and eliminate harsh shadows. The camera angle is a slightly elevated 45-degree shot to showcase its clean lines. Ultra-realistic, with sharp focus on the steam rising from the coffee. Square image."))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("product_mockup.png"), imgBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("A high-resolution, studio-lit product photograph of a minimalist ceramic coffee mug in matte black, presented on a polished concrete surface. The lighting is a three-point softbox setup designed to create soft, diffused highlights and eliminate harsh shadows. The camera angle is a slightly elevated 45-degree shot to showcase its clean lines. Ultra-realistic, with sharp focus on the steam rising from the coffee. Square image."),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("product_mockup.png", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "A high-resolution, studio-lit product photograph of a minimalist ceramic coffee mug in matte black, presented on a polished concrete surface. The lighting is a three-point softbox setup designed to create soft, diffused highlights and eliminate harsh shadows. The camera angle is a slightly elevated 45-degree shot to showcase its clean lines. Ultra-realistic, with sharp focus on the steam rising from the coffee. Square image."
  }'
 #### 5. 极简和负空间设计
非常适合为网站、演示文稿或营销材料创建背景,其中文本将被覆盖。
A minimalist composition featuring a single [subject] positioned in the
[bottom-right/top-left/etc.] of the frame. The background is a vast, empty
[color] canvas, creating significant negative space. Soft, subtle lighting.
[Aspect ratio].
A minimalist composition featuring a single, delicate red maple leaf
positioned in the bottom-right of the frame. The background is a vast, empty
off-white canvas, creating significant negative space for text. Soft,
diffused lighting from the top left. Square image.
from google import genai
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="A minimalist composition featuring a single, delicate red maple leaf positioned in the bottom-right of the frame. The background is a vast, empty off-white canvas, creating significant negative space for text. Soft, diffused lighting from the top left. Square image.",
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("minimalist_design.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "A minimalist composition featuring a single, delicate red maple leaf positioned in the bottom-right of the frame. The background is a vast, empty off-white canvas, creating significant negative space for text. Soft, diffused lighting from the top left. Square image.",
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("minimalist_design.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Base64;

Client client = new Client();

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "A minimalist composition featuring a single, delicate red maple leaf positioned in the bottom-right of the frame. The background is a vast, empty off-white canvas, creating significant negative space for text. Soft, diffused lighting from the top left. Square image."))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("minimalist_design.png"), imgBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("A minimalist composition featuring a single, delicate red maple leaf positioned in the bottom-right of the frame. The background is a vast, empty off-white canvas, creating significant negative space for text. Soft, diffused lighting from the top left. Square image."),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("minimalist_design.png", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "A minimalist composition featuring a single, delicate red maple leaf positioned in the bottom-right of the frame. The background is a vast, empty off-white canvas, creating significant negative space for text. Soft, diffused lighting from the top left. Square image."
  }'
 #### 6. 连续艺术(漫画面板/故事板)
基于角色一致性和场景描述来创建用于视觉叙事的面板。为了保证文本的准确性和讲故事的能力,这些提示与 Gemini 3 Pro 和 Gemini 3.1 Flash Image 配合使用效果最佳。
Make a 3 panel comic in a [style]. Put the character in a [type of scene].
Make a 3 panel comic in a gritty, noir art style with high-contrast black and white inks. Put the character in a humurous scene.
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/man_in_white_glasses.jpg', 'rb') as f:
    image_bytes = f.read()
text_input = "Make a 3 panel comic in a gritty, noir art style with high-contrast black and white inks. Put the character in a humurous scene."

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {"type": "text", "text": text_input},
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/jpeg"
        }
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("comic_panel.jpg", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const imagePath = "/path/to/your/man_in_white_glasses.jpg";
  const imageData = fs.readFileSync(imagePath);
  const base64Image = imageData.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      { type: "text", text: "Make a 3 panel comic in a gritty, noir art style with high-contrast black and white inks. Put the character in a humurous scene." },
      {
        type: "image",
        mime_type: "image/jpeg",
        data: base64Image
      },
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("comic_panel.jpg", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] imageBytes = Files.readAllBytes(Paths.get("/path/to/your/man_in_white_glasses.jpg"));
String base64Image = Base64.getEncoder().encodeToString(imageBytes);
String textInput =
    "Make a 3 panel comic in a gritty, noir art style with high-contrast black and white inks. Put the character in a humurous scene.";

Content textContent = TextContent.builder().text(textInput).build();
Content imageContent =
    ImageContent.builder()
        .data(base64Image)
        .mimeType(ImageContentMimeType.IMAGE_JPEG)
        .build();

List<Content> contents = Arrays.asList(textContent, imageContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("comic_panel.jpg"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    imageBytes, err := os.ReadFile("/path/to/your/man_in_white_glasses.jpg")
    if err != nil {
        log.Fatal(err)
    }
    base64Image := base64.StdEncoding.EncodeToString(imageBytes)
    textInput := "Make a 3 panel comic in a gritty, noir art style with high-contrast black and white inks. Put the character in a humurous scene."

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64Image),
            MimeType: interactions.ImageContentMimeTypeImageJpeg.ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("comic_panel.jpg", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": [
      {"type": "text", "text": "Make a 3 panel comic in a gritty, noir art style with high-contrast black and white inks. Put the character in a humurous scene."},
      {"type": "image", "data": "[BASE64_IMAGE_DATA]", "mime_type": "image/jpeg"}
    ]
  }'
输入 | 输出 |
|---|---|
|
|
 输入图像
 以坚韧的黑色艺术风格制作 3 面板漫画......
7. 事实依据与 Google 搜索 #
使用 Google 搜索根据最近或实时信息生成图像。这对于新闻、天气和其他时间敏感的主题非常有用。
Make a simple but stylish graphic of last night's Arsenal game in the Champion's League
from google import genai
from google.genai import types
import base64

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="Make a simple but stylish graphic of last night's Arsenal game in the Champion's League",
    tools=[{"type": "google_search"}],
    response_format={"type": "image", "aspect_ratio": "16:9"},
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("football-score.jpg", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: "Make a simple but stylish graphic of last night's Arsenal game in the Champion's League",
    tools: [{ type: "google_search" }],
    response_format: { type: "image", aspect_ratio: "16:9", image_size: "2K" },
  });

  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("football-score.jpg", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.GoogleSearch;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;

Client client = new Client();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .aspectRatio(ImageResponseFormatAspectRatio.of("16:9"))
                .build()));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Make a simple but stylish graphic of last night's Arsenal game in the Champion's League"))
        .tools(Arrays.asList(new GoogleSearch()))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] imgBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("football-score.jpg"), imgBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            AspectRatio: interactions.ImageResponseFormatAspectRatio("16:9").ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput("Make a simple but stylish graphic of last night's Arsenal game in the Champion's League"),
            Tools: []interactions.Tool{
                interactions.NewTool(interactions.GoogleSearch{}),
            },
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    imgBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("football-score.jpg", imgBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "Make a simple but stylish graphic of last nights Arsenal game in the Champions League",
    "tools": [{"type": "google_search"}],
    "response_format": {
      "type": "image",
      "aspect_ratio": "16:9"
    }
  }'
 ### 编辑图像的提示
这些示例展示了如何在文本提示旁边提供图像以进行编辑、合成和风格转换。
1. 添加和删除元素 #
提供图像并描述您的更改。该模型将与原始图像的风格、灯光和视角相匹配。
Using the provided image of [subject], please [add/remove/modify] [element]
to/from the scene. Ensure the change is [description of how the change should
integrate].
"Using the provided image of my cat, please add a small, knitted wizard hat
on its head. Make it look like it's sitting comfortably and matches the soft
lighting of the photo."
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/cat_photo.png', 'rb') as f:
    image_bytes = f.read()
text_input = """Using the provided image of my cat, please add a small, knitted wizard hat on its head. Make it look like it's sitting comfortably and not falling off."""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {"type": "text", "text": text_input},
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        }
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("cat_with_hat.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const imagePath = "/path/to/your/cat_photo.png";
  const imageData = fs.readFileSync(imagePath);
  const base64Image = imageData.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      { type: "text", text: "Using the provided image of my cat, please add a small, knitted wizard hat on its head. Make it look like it's sitting comfortably and not falling off." },
      {
        type: "image",
        mime_type: "image/png",
        data: base64Image
      },
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("cat_with_hat.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] imageBytes = Files.readAllBytes(Paths.get("/path/to/your/cat_photo.png"));
String base64Image = Base64.getEncoder().encodeToString(imageBytes);
String textInput =
    "Using the provided image of my cat, please add a small, knitted wizard hat on its head. Make it look like it's sitting comfortably and not falling off.";

Content textContent = TextContent.builder().text(textInput).build();
Content imageContent =
    ImageContent.builder()
        .data(base64Image)
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();

List<Content> contents = Arrays.asList(textContent, imageContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("cat_with_hat.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    imageBytes, err := os.ReadFile("/path/to/your/cat_photo.png")
    if err != nil {
        log.Fatal(err)
    }
    base64Image := base64.StdEncoding.EncodeToString(imageBytes)
    textInput := "Using the provided image of my cat, please add a small, knitted wizard hat on its head. Make it look like it's sitting comfortably and not falling off."

    contents := []interactions.Content{
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64Image),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("cat_with_hat.png", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
            {\"type\": \"text\", \"text\": \"Using the provided image of my cat, please add a small, knitted wizard hat on its head. Make it look like it's sitting comfortably and not falling off.\"},
            {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA]\"}
        ]
    }"
输入 | 输出 |
|---|---|
|
|
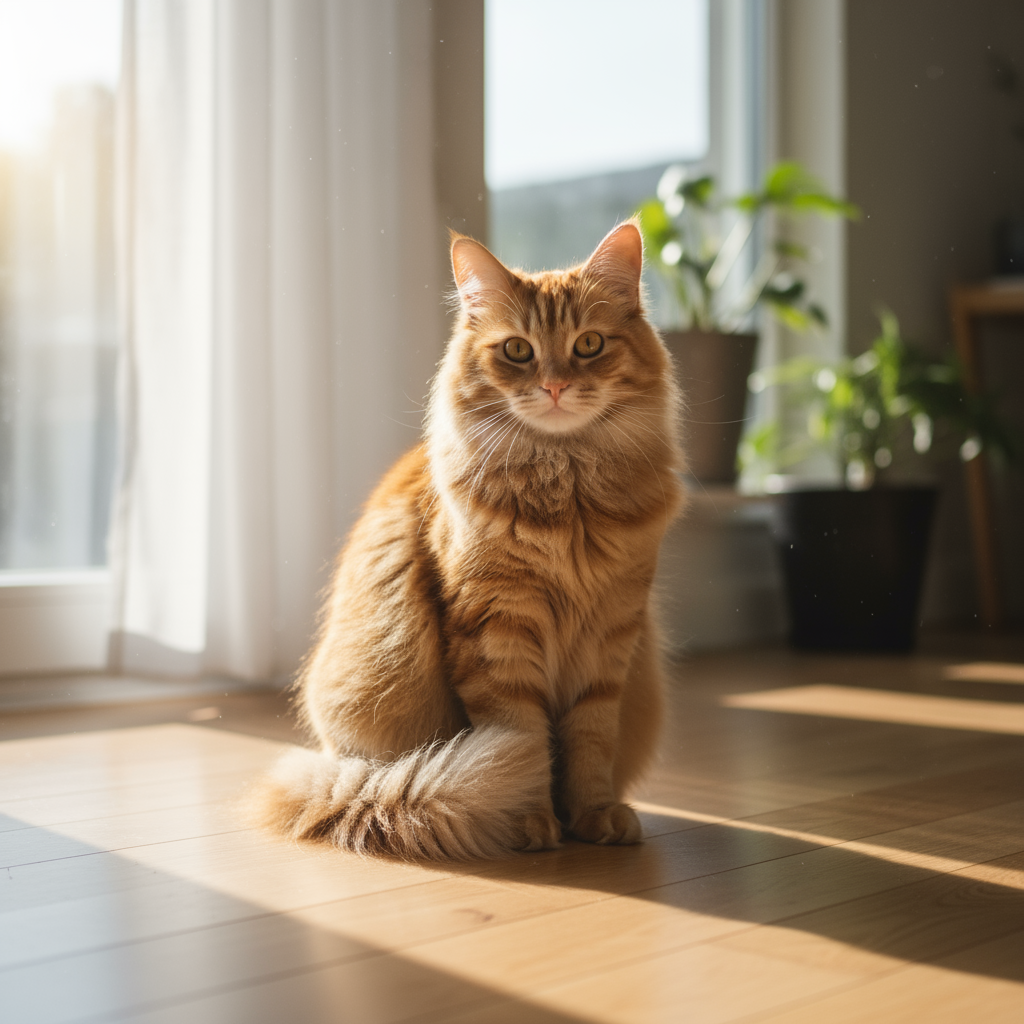 一只毛茸茸的姜黄色猫的真实照片...
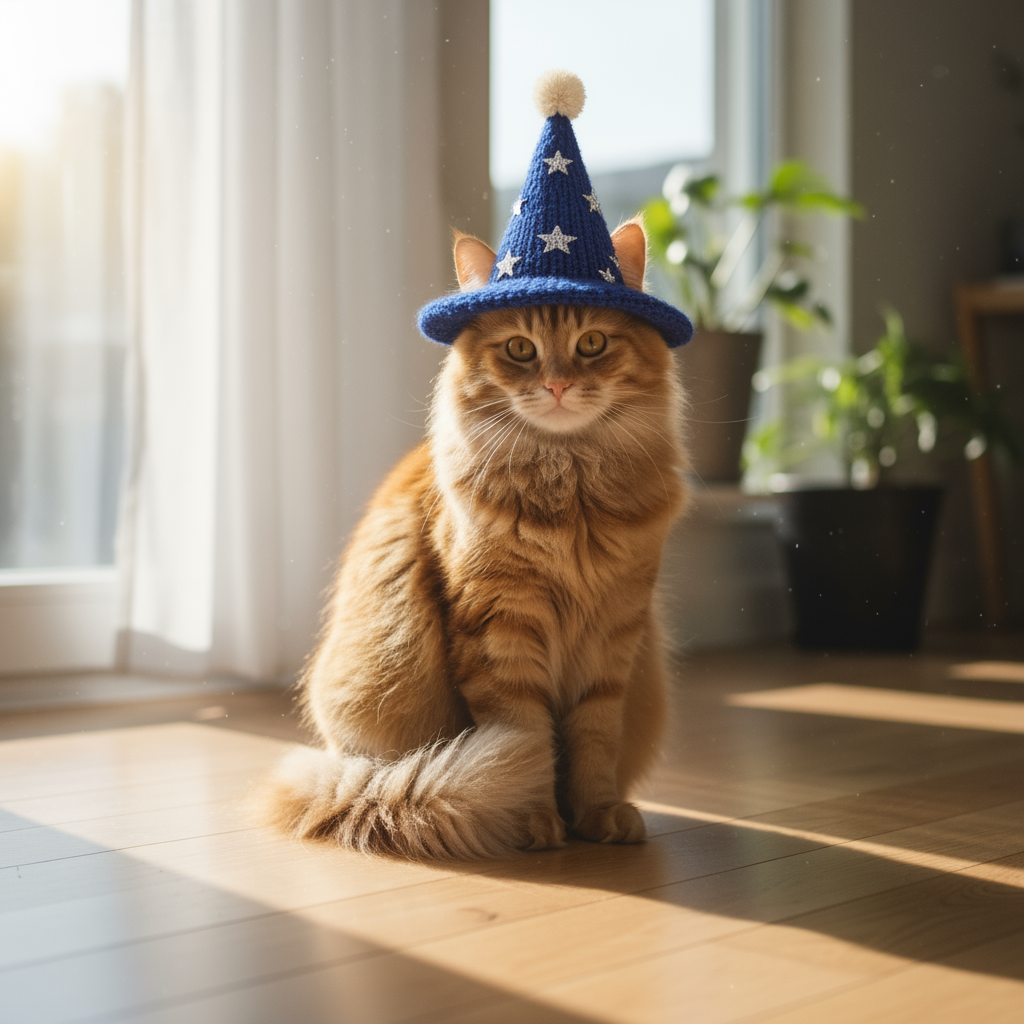 使用提供的我的猫的图像,请添加一顶小针织巫师帽......
2. 修复(语义掩蔽) #
以对话方式定义“蒙版”来编辑图像的特定部分,同时保持其余部分不变。
Using the provided image, change only the [specific element] to [new
element/description]. Keep everything else in the image exactly the same,
preserving the original style, lighting, and composition.
"Using the provided image of a living room, change only the blue sofa to be
a vintage, brown leather chesterfield sofa. Keep the rest of the room,
including the pillows on the sofa and the lighting, unchanged."
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/living_room.png', 'rb') as f:
    image_bytes = f.read()
text_input = """Using the provided image of a living room, change only the blue sofa to be a vintage, brown leather chesterfield sofa. Keep the rest of the room, including the pillows on the sofa and the lighting, unchanged."""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {"type": "text", "text": text_input}
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("living_room_edited.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const imagePath = "/path/to/your/living_room.png";
  const imageData = fs.readFileSync(imagePath);
  const base64Image = imageData.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      {
        type: "image",
        mime_type: "image/png",
        data: base64Image
      },
      { type: "text", text: "Using the provided image of a living room, change only the blue sofa to be a vintage, brown leather chesterfield sofa. Keep the rest of the room, including the pillows on the sofa and the lighting, unchanged." },
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("living_room_edited.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] imageBytes = Files.readAllBytes(Paths.get("/path/to/your/living_room.png"));
String base64Image = Base64.getEncoder().encodeToString(imageBytes);
String textInput =
    "Using the provided image of a living room, change only the blue sofa to be a vintage, brown leather chesterfield sofa. Keep the rest of the room, including the pillows on the sofa and the lighting, unchanged.";

Content imageContent =
    ImageContent.builder()
        .data(base64Image)
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content textContent = TextContent.builder().text(textInput).build();

List<Content> contents = Arrays.asList(imageContent, textContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("living_room_edited.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    imageBytes, err := os.ReadFile("/path/to/your/living_room.png")
    if err != nil {
        log.Fatal(err)
    }
    base64Image := base64.StdEncoding.EncodeToString(imageBytes)
    textInput := "Using the provided image of a living room, change only the blue sofa to be a vintage, brown leather chesterfield sofa. Keep the rest of the room, including the pillows on the sofa and the lighting, unchanged."

    contents := []interactions.Content{
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64Image),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("living_room_edited.png", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
        {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA]\"},
        {\"type\": \"text\", \"text\": \"Using the provided image of a living room, change only the blue sofa to be a vintage, brown leather chesterfield sofa. Keep the rest of the room, including the pillows on the sofa and the lighting, unchanged.\"}
      ]
    }"
输入 | 输出 |
|---|---|
|
|
 现代、光线充足的客厅的广角镜头......
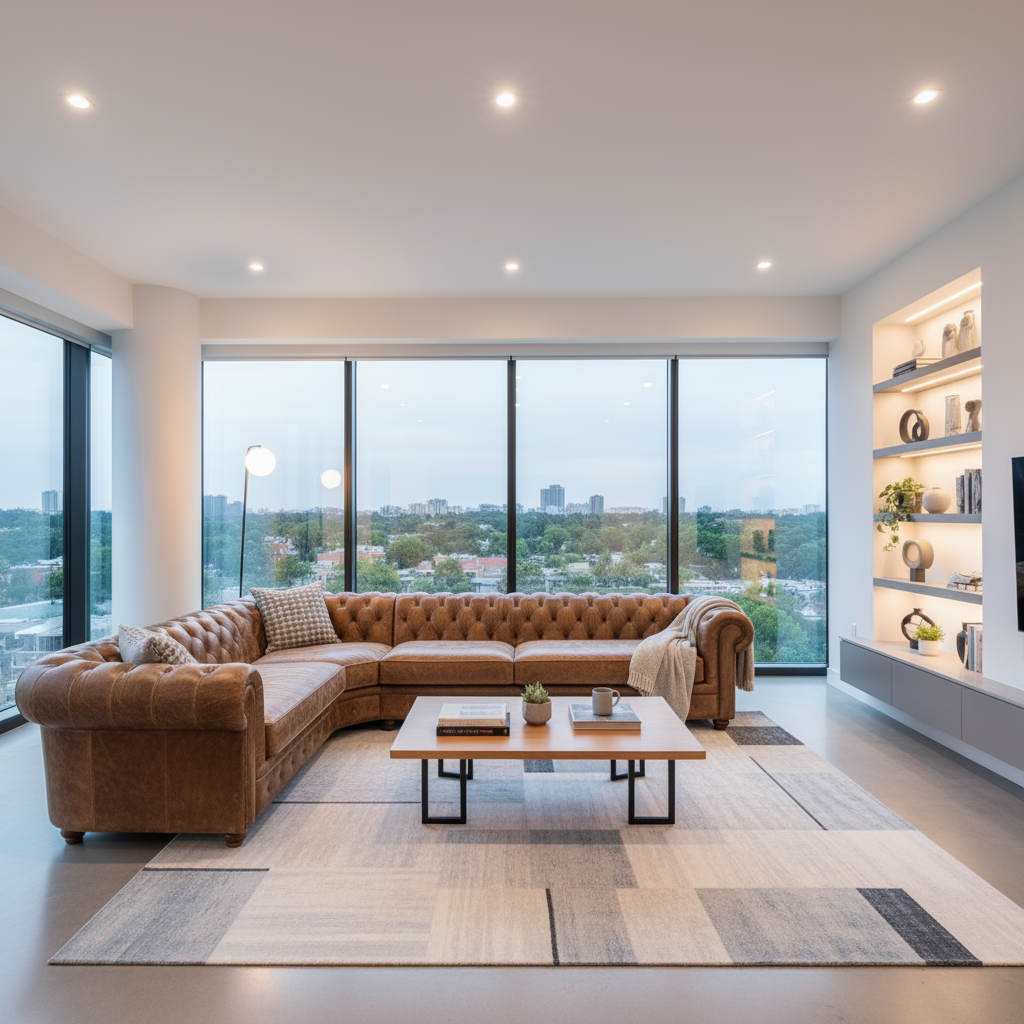 使用提供的客厅图像,仅将蓝色沙发更改为复古棕色皮革切斯特菲尔德沙发......
3. 风格转移 #
提供图像并要求模型以不同的艺术风格重新创建其内容。
Transform the provided photograph of [subject] into the artistic style of [artist/art style]. Preserve the original composition but render it with [description of stylistic elements].
"Transform the provided photograph of a modern city street at night into the artistic style of Vincent van Gogh's 'Starry Night'. Preserve the original composition of buildings and cars, but render all elements with swirling, impasto brushstrokes and a dramatic palette of deep blues and bright yellows."
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/city.png', 'rb') as f:
    image_bytes = f.read()
text_input = """Transform the provided photograph of a modern city street at night into the artistic style of Vincent van Gogh's 'Starry Night'. Preserve the original composition of buildings and cars, but render all elements with swirling, impasto brushstrokes and a dramatic palette of deep blues and bright yellows."""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {
            "type": "image",
            "data": base64.b64encode(image_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {"type": "text", "text": text_input}
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("city_style_transfer.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});
  const imageData = fs.readFileSync("/path/to/your/city.png");
  const base64Image = imageData.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      {
        type: "image",
        mime_type: "image/png",
        data: base64Image
      },
      { type: "text", text: "Transform the provided photograph of a modern city street at night into the artistic style of Vincent van Gogh's 'Starry Night'. Preserve the original composition of buildings and cars, but render all elements with swirling, impasto brushstrokes and a dramatic palette of deep blues and bright yellows." },
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("city_style_transfer.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] imageBytes = Files.readAllBytes(Paths.get("/path/to/your/city.png"));
String base64Image = Base64.getEncoder().encodeToString(imageBytes);
String textInput =
    "Transform the provided photograph of a modern city street at night into the artistic style of Vincent van Gogh's 'Starry Night'. Preserve the original composition of buildings and cars, but render all elements with swirling, impasto brushstrokes and a dramatic palette of deep blues and bright yellows.";

Content imageContent =
    ImageContent.builder()
        .data(base64Image)
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content textContent = TextContent.builder().text(textInput).build();

List<Content> contents = Arrays.asList(imageContent, textContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("city_style_transfer.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    imageBytes, err := os.ReadFile("/path/to/your/city.png")
    if err != nil {
        log.Fatal(err)
    }
    base64Image := base64.StdEncoding.EncodeToString(imageBytes)
    textInput := "Transform the provided photograph of a modern city street at night into the artistic style of Vincent van Gogh's 'Starry Night'. Preserve the original composition of buildings and cars, but render all elements with swirling, impasto brushstrokes and a dramatic palette of deep blues and bright yellows."

    contents := []interactions.Content{
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64Image),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("city_style_transfer.png", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
        {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA]\"},
        {\"type\": \"text\", \"text\": \"Transform the provided photograph of a modern city street at night into the artistic style of Vincent van Gogh's 'Starry Night'. Preserve the original composition of buildings and cars, but render all elements with swirling, impasto brushstrokes and a dramatic palette of deep blues and bright yellows.\"}
      ]
    }"
输入 | 输出 |
|---|---|
|
|
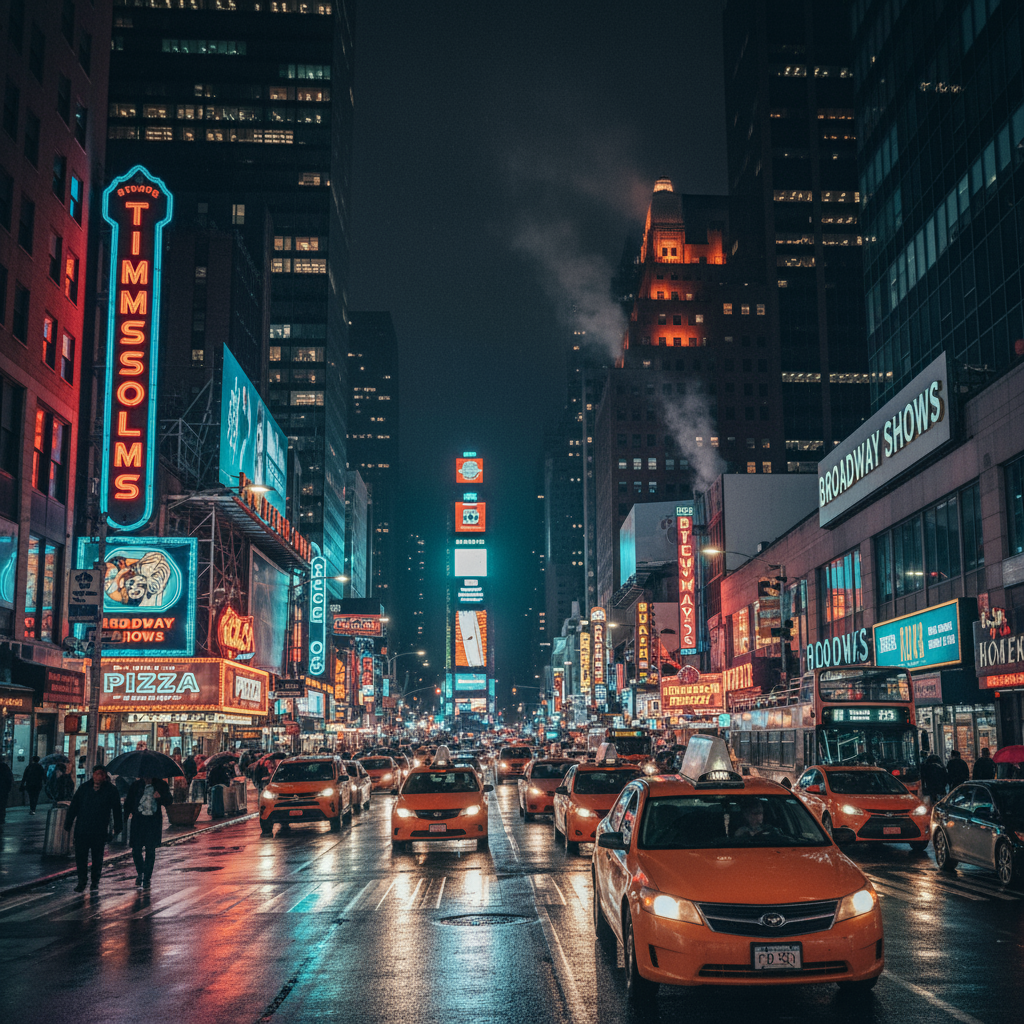 繁忙城市街道的逼真高分辨率照片......
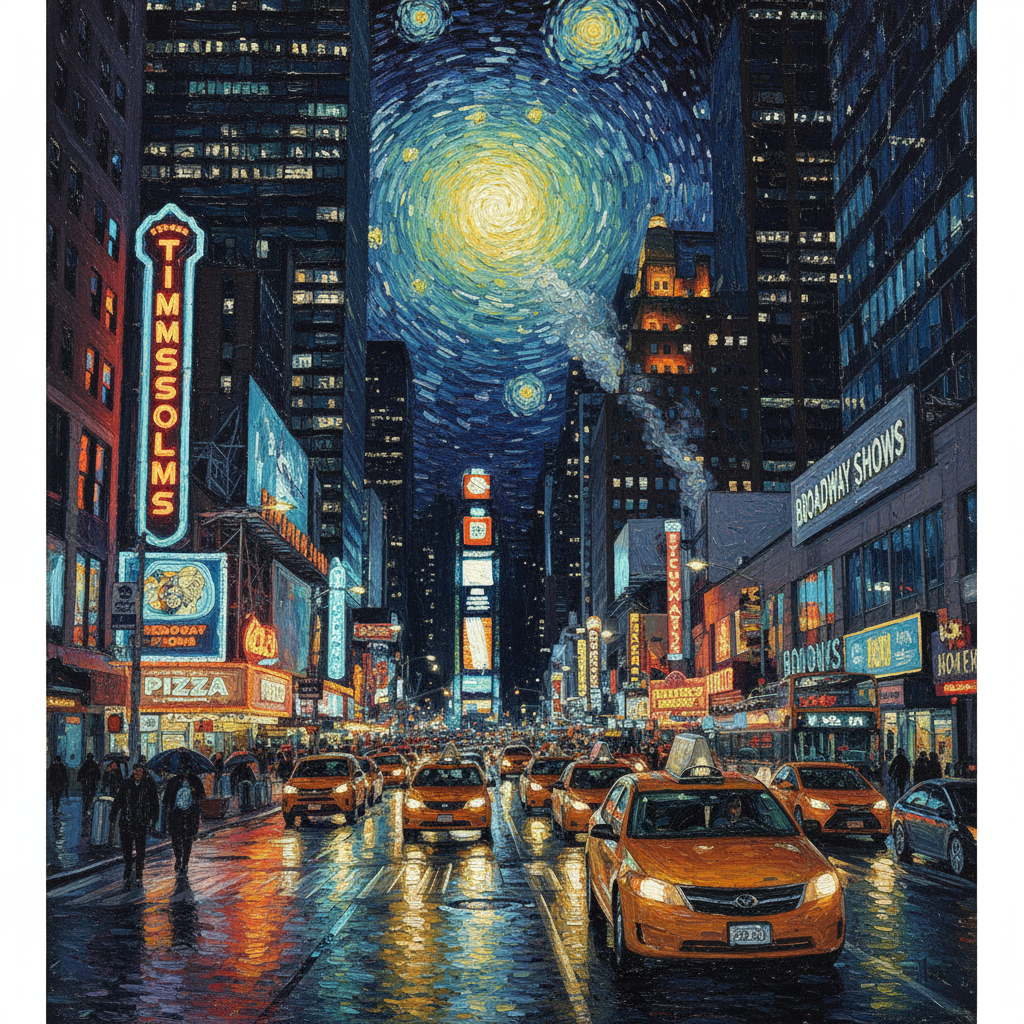 改造所提供的现代城市街道夜间照片...
4. 高级合成:组合多个图像 #
提供多个图像作为上下文来创建新的复合场景。这非常适合产品模型或创意拼贴。
Create a new image by combining the elements from the provided images. Take
the [element from image 1] and place it with/on the [element from image 2].
The final image should be a [description of the final scene].
"Create a professional e-commerce fashion photo. Take the blue floral dress
from the first image and let the woman from the second image wear it.
Generate a realistic, full-body shot of the woman wearing the dress, with
the lighting and shadows adjusted to match the outdoor environment."
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/dress.png', 'rb') as f:
    dress_bytes = f.read()
with open('/path/to/your/model.png', 'rb') as f:
    model_bytes = f.read()
text_input = """Create a professional e-commerce fashion photo. Take the blue floral dress from the first image and let the woman from the second image wear it. Generate a realistic, full-body shot of the woman wearing the dress, with the lighting and shadows adjusted to match the outdoor environment."""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
        {
            "type": "image",
            "data": base64.b64encode(dress_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {
            "type": "image",
            "data": base64.b64encode(model_bytes).decode('utf-8'),
            "mime_type": "image/png"
        },
        {"type": "text", "text": text_input}
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("fashion_ecommerce_shot.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const imagePath1 = "/path/to/your/dress.png";
  const imageData1 = fs.readFileSync(imagePath1);
  const base64Image1 = imageData1.toString("base64");
  const imagePath2 = "/path/to/your/model.png";
  const imageData2 = fs.readFileSync(imagePath2);
  const base64Image2 = imageData2.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      {
        type: "image",
        mime_type: "image/png",
        data: base64Image1
      },
      {
        type: "image",
        mime_type: "image/png",
        data: base64Image2
      },
      { type: "text", text: "Create a professional e-commerce fashion photo. Take the blue floral dress from the first image and let the woman from the second image wear it. Generate a realistic, full-body shot of the woman wearing the dress, with the lighting and shadows adjusted to match the outdoor environment." },
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("fashion_ecommerce_shot.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] dressBytes = Files.readAllBytes(Paths.get("/path/to/your/dress.png"));
byte[] modelBytes = Files.readAllBytes(Paths.get("/path/to/your/model.png"));
String textInput =
    "Create a professional e-commerce fashion photo. Take the blue floral dress from the first image and let the woman from the second image wear it. Generate a realistic, full-body shot of the woman wearing the dress, with the lighting and shadows adjusted to match the outdoor environment.";

Content dressContent =
    ImageContent.builder()
        .data(Base64.getEncoder().encodeToString(dressBytes))
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content modelContent =
    ImageContent.builder()
        .data(Base64.getEncoder().encodeToString(modelBytes))
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content textContent = TextContent.builder().text(textInput).build();

List<Content> contents = Arrays.asList(dressContent, modelContent, textContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("fashion_ecommerce_shot.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    dressBytes, err := os.ReadFile("/path/to/your/dress.png")
    if err != nil {
        log.Fatal(err)
    }
    modelBytes, err := os.ReadFile("/path/to/your/model.png")
    if err != nil {
        log.Fatal(err)
    }
    textInput := "Create a professional e-commerce fashion photo. Take the blue floral dress from the first image and let the woman from the second image wear it. Generate a realistic, full-body shot of the woman wearing the dress, with the lighting and shadows adjusted to match the outdoor environment."

    contents := []interactions.Content{
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64.StdEncoding.EncodeToString(dressBytes)),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64.StdEncoding.EncodeToString(modelBytes)),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("fashion_ecommerce_shot.png", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
            {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA_1]\"},
            {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA_2]\"},
            {\"type\": \"text\", \"text\": \"Create a professional e-commerce fashion photo. Take the blue floral dress from the first image and let the woman from the second image wear it. Generate a realistic, full-body shot of the woman wearing the dress, with the lighting and shadows adjusted to match the outdoor environment.\"}
      }]
    }"
输入 1 | 输入 2 | 输出 |
|---|---|---|
|
|
|
 中性背景中的蓝色花卉夏裙
 一个头发盘成发髻的女人的全身照......
 一位在户外环境中穿着蓝色花卉夏装的女人
5. 高保真细节保留 #
为了确保在编辑过程中保留关键细节(例如面孔或徽标),请在编辑请求中详细描述它们。
Using the provided images, place [element from image 2] onto [element from
image 1]. Ensure that the features of [element from image 1] remain
completely unchanged. The added element should [description of how the
element should integrate].
"Take the first image of the woman with brown hair, blue eyes, and a neutral
expression. Add the logo from the second image onto her black t-shirt.
Ensure the woman's face and features remain completely unchanged. The logo
should look like it's naturally printed on the fabric, following the folds
of the shirt."
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/woman.png', 'rb') as f:
    woman_bytes = f.read()
with open('/path/to/your/logo.png', 'rb') as f:
    logo_bytes = f.read()
text_input = """Take the first image of the woman with brown hair, blue eyes, and a neutral expression. Add the logo from the second image onto her black t-shirt. Ensure the woman's face and features remain completely unchanged. The logo should look like it's naturally printed on the fabric, following the folds of the shirt."""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
      {"type": "image", "mime_type":"image/png", "data": base64.b64encode(woman_bytes).decode('utf-8')},
      {"type": "image", "mime_type":"image/png", "data": base64.b64encode(logo_bytes).decode('utf-8')},
      {"type": "text", "text": text_input}
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("woman_with_logo.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const imagePath1 = "/path/to/your/woman.png";
  const imageData1 = fs.readFileSync(imagePath1);
  const base64Image1 = imageData1.toString("base64");
  const imagePath2 = "/path/to/your/logo.png";
  const imageData2 = fs.readFileSync(imagePath2);
  const base64Image2 = imageData2.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      {"type": "image", "mime_type":"image/png", "data": base64Image1},
      {"type": "image", "mime_type":"image/png", "data": base64Image2},
      {"type": "text", "text": "Take the first image of the woman with brown hair, blue eyes, and a neutral expression. Add the logo from the second image onto her black t-shirt. Ensure the woman's face and features remain completely unchanged. The logo should look like it's naturally printed on the fabric, following the folds of the shirt."},
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("woman_with_logo.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] womanBytes = Files.readAllBytes(Paths.get("/path/to/your/woman.png"));
byte[] logoBytes = Files.readAllBytes(Paths.get("/path/to/your/logo.png"));
String textInput =
    "Take the first image of the woman with brown hair, blue eyes, and a neutral expression. Add the logo from the second image onto her black t-shirt. Ensure the woman's face and features remain completely unchanged. The logo should look like it's naturally printed on the fabric, following the folds of the shirt.";

Content womanContent =
    ImageContent.builder()
        .data(Base64.getEncoder().encodeToString(womanBytes))
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content logoContent =
    ImageContent.builder()
        .data(Base64.getEncoder().encodeToString(logoBytes))
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content textContent = TextContent.builder().text(textInput).build();

List<Content> contents = Arrays.asList(womanContent, logoContent, textContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("woman_with_logo.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    womanBytes, err := os.ReadFile("/path/to/your/woman.png")
    if err != nil {
        log.Fatal(err)
    }
    logoBytes, err := os.ReadFile("/path/to/your/logo.png")
    if err != nil {
        log.Fatal(err)
    }
    textInput := "Take the first image of the woman with brown hair, blue eyes, and a neutral expression. Add the logo from the second image onto her black t-shirt. Ensure the woman's face and features remain completely unchanged. The logo should look like it's naturally printed on the fabric, following the folds of the shirt."

    contents := []interactions.Content{
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64.StdEncoding.EncodeToString(womanBytes)),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64.StdEncoding.EncodeToString(logoBytes)),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("woman_with_logo.png", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
        {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA_1]\"},
        {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA_2]\"},
        {\"type\": \"text\", \"text\": \"Take the first image of the woman with brown hair, blue eyes, and a neutral expression. Add the logo from the second image onto her black t-shirt. Ensure the woman's face and features remain completely unchanged. The logo should look like it's naturally printed on the fabric, following the folds of the shirt.\"}
      ]
    }"
输入 1 | 输入 2 | 输出 |
|---|---|---|
|
|
|
 一个棕色头发和蓝色眼睛的女人的专业爆头...
 带字母 G 和 A 的现代品牌标识符
 拍摄第一张棕色头发、蓝色眼睛、表情中性的女人的照片……
6. 赋予生活一些东西 #
上传粗略的草图或绘图,并要求模特将其细化为成品图像。
Turn this rough [medium] sketch of a [subject] into a [style description]
photo. Keep the [specific features] from the sketch but add [new details/materials].
"Turn this rough pencil sketch of a futuristic car into a polished photo of the finished concept car in a showroom. Keep the sleek lines and low profile from the sketch but add metallic blue paint and neon rim lighting."
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/car_sketch.png', 'rb') as f:
    sketch_bytes = f.read()
text_input = """Turn this rough pencil sketch of a futuristic car into a polished photo of the finished concept car in a showroom. Keep the sleek lines and low profile from the sketch but add metallic blue paint and neon rim lighting."""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=[
      {"type": "image", "mime_type":"image/png", "data": base64.b64encode(sketch_bytes).decode('utf-8')},
      {"type": "text", "text": text_input}
    ],
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("car_photo.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import { GoogleGenAI } from "@google/genai";
import * as fs from "node:fs";

async function main() {
  const ai = new GoogleGenAI({});

  const imagePath = "/path/to/your/car_sketch.png";
  const imageData = fs.readFileSync(imagePath);
  const base64Image = imageData.toString("base64");

  const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: [
      {"type": "image", "mime_type":"image/png", "data": base64Image},
      {"type": "text", "text": "Turn this rough pencil sketch of a futuristic car into a polished photo of the finished concept car in a showroom. Keep the sleek lines and low profile from the sketch but add metallic blue paint and neon rim lighting."},
    ],
  });
  for (const step of interaction.steps) {
    if (step.type === "model_output") {
      for (const contentBlock of step.content || []) {
        if (contentBlock.type === "text") {
          console.log(contentBlock.text);
        } else if (contentBlock.type === "image") {
          if (contentBlock.data) {
          const buffer = Buffer.from(contentBlock.data, "base64");
          fs.writeFileSync("car_photo.png", buffer);
        }
        }
      }
    }
  }
}

await main();
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] sketchBytes = Files.readAllBytes(Paths.get("/path/to/your/car_sketch.png"));
String textInput =
    "Turn this rough pencil sketch of a futuristic car into a polished photo of the finished concept car in a showroom. Keep the sleek lines and low profile from the sketch but add metallic blue paint and neon rim lighting.";

Content sketchContent =
    ImageContent.builder()
        .data(Base64.getEncoder().encodeToString(sketchBytes))
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();
Content textContent = TextContent.builder().text(textInput).build();

List<Content> contents = Arrays.asList(sketchContent, textContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("car_photo.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
package main

import (
    "context"
    "encoding/base64"
    "fmt"
    "log"
    "os"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    sketchBytes, err := os.ReadFile("/path/to/your/car_sketch.png")
    if err != nil {
        log.Fatal(err)
    }
    textInput := "Turn this rough pencil sketch of a futuristic car into a polished photo of the finished concept car in a showroom. Keep the sleek lines and low profile from the sketch but add metallic blue paint and neon rim lighting."

    contents := []interactions.Content{
        interactions.NewContent(interactions.ImageContent{
            Data:     genai.Ptr(base64.StdEncoding.EncodeToString(sketchBytes)),
            MimeType: interactions.ImageContentMimeTypeImagePng.ToPointer(),
        }),
        interactions.NewContent(interactions.TextContent{
            Text: textInput,
        }),
    }

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model: interactions.Model("gemini-nano-banana-2.1"),
            Input: interactions.NewInteractionsInput(contents),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }

    for _, step := range res.Interaction.Steps {
        if step.ModelOutputStep != nil {
            for _, contentBlock := range step.ModelOutputStep.Content {
                if contentBlock.TextContent != nil {
                    fmt.Println(contentBlock.TextContent.Text)
                } else if contentBlock.ImageContent != nil && contentBlock.ImageContent.Data != nil {
                    outBytes, err := base64.StdEncoding.DecodeString(*contentBlock.ImageContent.Data)
                    if err != nil {
                        log.Fatal(err)
                    }
                    if err := os.WriteFile("car_photo.png", outBytes, 0644); err != nil {
                        log.Fatal(err)
                    }
                }
            }
        }
    }
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
    -H "x-goog-api-key: $GEMINI_API_KEY" \
    -H 'Content-Type: application/json' \
    -d "{
      \"model\": \"gemini-nano-banana-2.1\",
      \"input\": [
        {\"type\": \"image\", \"mime_type\":\"image/png\", \"data\": \"[BASE64_IMAGE_DATA]\"},
        {\"type\": \"text\", \"text\": \"Turn this rough pencil sketch of a futuristic car into a polished photo of the finished concept car in a showroom. Keep the sleek lines and low profile from the sketch but add metallic blue paint and neon rim lighting.\"}
      ]
    }"
输入 | 输出 |
|---|---|
|
|
 汽车的粗略草图
 抛光的汽车照片
7. 字符一致性:360 查看 #
您可以通过迭代提示不同角度来生成角色的 360 度视图。为了获得最佳结果,请在后续提示中包含先前生成的图像以保持一致性。对于复杂姿势,请包含所选姿势的参考图像。
A studio portrait of [person] against [background], [looking forward/in profile looking right/etc.]
A studio portrait of this man against white, in profile looking right
from google import genai
from PIL import Image
import base64

client = genai.Client()

with open('/path/to/your/man_in_white_glasses.jpg', 'rb') as f:
    image_bytes = f.read()
text_input = """A studio portrait of this man against white, in profile looking right"""

interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input={
      {"type": "text", "text": text_input},
      {"type": "image", "mime_type":"image/png", "data": base64.b64encode(image_bytes).decode('utf-8')}
    },
)

for step in interaction.steps:
    if step.type == "model_output":
        for content_block in step.content:
            if content_block.type == "text":
                print(content_block.text)
            elif content_block.type == "image":
                with open("man_right_profile.png", "wb") as f:
                    f.write(base64.b64decode(content_block.data))
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.Content;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.ImageContent;
import com.google.genai.gaos.models.interactions.ImageContentMimeType;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ModelOutputStep;
import com.google.genai.gaos.models.interactions.Step;
import com.google.genai.gaos.models.interactions.TextContent;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.nio.file.Files;
import java.nio.file.Paths;
import java.util.Arrays;
import java.util.Base64;
import java.util.List;

Client client = new Client();

byte[] imageBytes = Files.readAllBytes(Paths.get("/path/to/your/man_in_white_glasses.jpg"));
String textInput = "A studio portrait of this man against white, in profile looking right";

Content textContent = TextContent.builder().text(textInput).build();
Content imageContent =
    ImageContent.builder()
        .data(Base64.getEncoder().encodeToString(imageBytes))
        .mimeType(ImageContentMimeType.IMAGE_PNG)
        .build();

List<Content> contents = Arrays.asList(textContent, imageContent);

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.ofContent(contents))
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();

if (interaction.steps().isPresent()) {
  for (Step step : interaction.steps().get()) {
    if (step instanceof ModelOutputStep) {
      ModelOutputStep outputStep = (ModelOutputStep) step;
      if (outputStep.content().isPresent()) {
        for (Content contentBlock : outputStep.content().get()) {
          if (contentBlock instanceof TextContent) {
            System.out.println(((TextContent) contentBlock).text().orElse(""));
          } else if (contentBlock instanceof ImageContent) {
            ImageContent img = (ImageContent) contentBlock;
            if (img.data().isPresent()) {
              byte[] outBytes = Base64.getDecoder().decode(img.data().get());
              Files.write(Paths.get("man_right_profile.png"), outBytes);
            }
          }
        }
      }
    }
  }
}
输入 | 输出 1 | 输出 2 |
|---|---|---|
|
|
|
 戴白眼镜的男人向右看
 戴白眼镜的男人期待着
最佳实践 #
为了将您的结果从优秀提升到卓越,请将这些专业策略纳入您的工作流程中。
高度具体: 您提供的细节越多,您的控制权就越大。与其描述它是“幻想盔甲”,不如说:“华丽的精灵板甲,蚀刻有银叶图案,有高领和形状像猎鹰翅膀的肩甲。”
提供上下文和意图: 解释一下 目的 的图像。模型对上下文的理解将影响最终的输出。例如,“为高端、简约的护肤品牌创建徽标”会比仅仅“创建徽标”产生更好的结果。
迭代和细化: 不要指望第一次尝试就能获得完美的图像。利用模型的对话性质进行小的更改。跟进诸如“那太好了,但是你能让灯光暖一点吗?”之类的提示。或“保持一切不变,但将角色的表情改变得更严肃。”
使用分步说明: 对于包含许多元素的复杂场景,请将提示分成步骤。 “首先,创建一个黎明时分宁静、雾气弥漫的森林的背景。然后,在前景中添加一个长满青苔的古老石祭坛。最后,在祭坛顶部放置一把发光的剑。”
使用“语义否定提示”: 不要说“没有汽车”,而是积极地描述预期的场景:“一条空荡荡的、荒芜的街道,没有交通迹象。”
控制相机: 使用摄影和电影语言来控制构图。类似的术语
wide-angle shot,macro shot,low-angle perspective.
限制 #
为了获得最佳性能,请使用以下语言:EN、ar-EG、de-DE、es-MX、fr-FR、hi-IN、id-ID、it-IT、ja-JP、ko-KR、pt-BR、ru-RU、ua-UA、vi-VN、zh-CN。
图像生成不支持音频输入。仅 Gemini Nano Banana 2.1、Gemini 3.1 Flash Image 和 Gemini 3.1 Flash Lite Image 支持视频输入。
该模型并不总是遵循用户明确要求的图像输出的确切数量。
gemini-2.5-flash-image最多可使用 3 图像作为输入,效果最佳,同时gemini-3-pro-image支持高保真5图像,最多支持14图像。gemini-nano-banana-2.1和gemini-3.1-flash-image在单个工作流程中支持最多 4 字符的字符相似度和最多 10 对象的保真度。为图像生成文本时,如果您首先生成文本,然后请求带有文本的图像,则 Gemini 效果最佳。
gemini-nano-banana-2.1和gemini-3.1-flash-image事实依据和 Google 搜索目前不支持使用来自网络搜索的真实世界人物图像。所有生成的图像都包含 SynthID水印.
可选配置 #
您可以选择使用以下命令配置输出格式、宽高比和图像大小 response_format 参数。
输出格式 #
该模型默认返回文本和图像响应。您可以通过在 response_format 参数。
要请求多种模式(例如,文本和生成的图像),请将格式条目数组传递给 response_format 相反。
interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input="Write a short poem about a starry night and generate an image of it.",
    response_format=[
        {"type": "text"},
        {"type": "image"},
    ],
)
const interaction = await ai.interactions.create({
  model: "gemini-nano-banana-2.1",
  input: "Write a short poem about a starry night and generate an image of it.",
  response_format: [
    { type: "text" },
    { type: "image" },
  ],
});
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.interactions.TextResponseFormat;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;
import java.util.Arrays;

Client client = new Client();

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        Arrays.asList(
            ResponseFormat.of(TextResponseFormat.builder().build()),
            ResponseFormat.of(ImageResponseFormat.builder().build())));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(
            InteractionsInput.of(
                "Write a short poem about a starry night and generate an image of it."))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();
package main

import (
    "context"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    format := interactions.NewCreateModelInteractionResponseFormat([]interactions.ResponseFormat{
        interactions.NewResponseFormat(interactions.TextResponseFormat{}),
        interactions.NewResponseFormat(interactions.ImageResponseFormat{}),
    })

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput("Write a short poem about a starry night and generate an image of it."),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }
    _ = res
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "Write a short poem about a starry night and generate an image of it.",
    "response_format": [
      { "type": "text" },
      { "type": "image" }
    ]
  }'
gemini-api image "Write a short poem about a starry night and generate an image of it." \
  --body '{"response_format":[{"type":"text"},{"type":"image"}]}' \
  --raw-response -o json
宽高比和图像尺寸 #
默认情况下,模型将输出图像大小与输入图像大小相匹配,或者生成 1:1 正方形。您可以使用以下命令控制输出图像的纵横比和大小 aspect_ratio 和 image_size 下的字段 response_format 当 type 设置为 "image".
interaction = client.interactions.create(
    model="gemini-nano-banana-2.1",
    input=prompt,
    response_format={
        "type": "image",
        "aspect_ratio": "16:9",
        "image_size": "2K",
    },
)
const interaction = await ai.interactions.create({
    model: "gemini-nano-banana-2.1",
    input: prompt,
    response_format: {
      type: "image",
      aspect_ratio: "16:9",
      image_size: "2K",
    },
  });
import com.google.genai.Client;
import com.google.genai.gaos.models.interactions.CreateModelInteraction;
import com.google.genai.gaos.models.interactions.CreateModelInteractionResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormat;
import com.google.genai.gaos.models.interactions.ImageResponseFormatAspectRatio;
import com.google.genai.gaos.models.interactions.ImageResponseFormatImageSize;
import com.google.genai.gaos.models.interactions.Interaction;
import com.google.genai.gaos.models.interactions.InteractionsInput;
import com.google.genai.gaos.models.interactions.Model;
import com.google.genai.gaos.models.interactions.ResponseFormat;
import com.google.genai.gaos.models.operations.CreateInteractionRequestBody;

Client client = new Client();
String prompt = "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme";

CreateModelInteractionResponseFormat format =
    CreateModelInteractionResponseFormat.of(
        ResponseFormat.of(
            ImageResponseFormat.builder()
                .aspectRatio(ImageResponseFormatAspectRatio.of("16:9"))
                .imageSize(ImageResponseFormatImageSize.TWO_K)
                .build()));

CreateModelInteraction params =
    CreateModelInteraction.builder()
        .model(Model.of("gemini-nano-banana-2.1"))
        .input(InteractionsInput.of(prompt))
        .responseFormat(format)
        .build();

Interaction interaction =
    client.interactions.create(CreateInteractionRequestBody.of(params)).interaction().get();
package main

import (
    "context"
    "log"

    "google.golang.org/genai"
    "google.golang.org/genai/interactions/models/interactions"
    "google.golang.org/genai/interactions/models/operations"
)

func main() {
    ctx := context.Background()
    client, err := genai.NewClient(ctx, nil)
    if err != nil {
        log.Fatal(err)
    }

    prompt := "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme"

    format := interactions.NewCreateModelInteractionResponseFormat(
        interactions.NewResponseFormat(interactions.ImageResponseFormat{
            AspectRatio: interactions.ImageResponseFormatAspectRatio("16:9").ToPointer(),
            ImageSize:   interactions.ImageResponseFormatImageSizeTwoK.ToPointer(),
        }),
    )

    res, err := client.Interactions.Create(ctx, operations.CreateInteractionRequest{
        Body: operations.NewCreateInteractionRequestBody(interactions.CreateModelInteraction{
            Model:          interactions.Model("gemini-nano-banana-2.1"),
            Input:          interactions.NewInteractionsInput(prompt),
            ResponseFormat: genai.Ptr(format),
        }),
    })
    if err != nil {
        log.Fatal(err)
    }
    _ = res
}
curl -s -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H 'Content-Type: application/json' \
  -H "Api-Revision: 2026-05-20" \
  -d '{
    "model": "gemini-nano-banana-2.1",
    "input": "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme",
    "response_format": {
      "type": "image",
      "aspect_ratio": "16:9",
      "image_size": "2K"
    }
  }'
gemini-api image "Create a picture of a nano banana dish in a fancy restaurant with a Gemini theme" \
  --aspect-ratio 16:9 \
  --image-size 2K \
  --out generated_image.png
下表列出了可用的不同比例和生成的图像的大小:
纵横比 | 1K分辨率 | 1K token | 2K分辨率 | 2K token | 4K分辨率 | 4K token |
|---|---|---|---|---|---|---|
1:1 | 1024x1024 | 1120 | 2048x2048 | 1680 | 4096x4096 | 2520 |
1:4 | 512x2048 | 1120 | 1024x4096 | 1680 | 2048x8192 | 2520 |
1:8 | 384x3072 | 1120 | 768x6144 | 1680 | 1536x12288 | 2520 |
2:3 | 848x1264 | 1120 | 1696x2528 | 1680 | 3392x5056 | 2520 |
3:2 | 1264x848 | 1120 | 2528x1696 | 1680 | 5056x3392 | 2520 |
3:4 | 896x1200 | 1120 | 1792x2400 | 1680 | 3584x4800 | 2520 |
4:1 | 2048x512 | 1120 | 4096x1024 | 1680 | 8192x2048 | 2520 |
4:3 | 1200x896 | 1120 | 2400x1792 | 1680 | 4800x3584 | 2520 |
4:5 | 928x1152 | 1120 | 1856x2304 | 1680 | 3712x4608 | 2520 |
5:4 | 1152x928 | 1120 | 2304x1856 | 1680 | 4608x3712 | 2520 |
8:1 | 3072x384 | 1120 | 6144x768 | 1680 | 12288x1536 | 2520 |
9:16 | 768x1376 | 1120 | 1536x2752 | 1680 | 3072x5504 | 2520 |
16:9 | 1376x768 | 1120 | 2752x1536 | 1680 | 5504x3072 | 2520 |
21:9 | 1584x672 | 1120 | 3168x1344 | 1680 | 6336x2688 | 2520 |
纵横比 | 512像素分辨率 | 0.5K token | 1K分辨率 | 1K token | 2K分辨率 | 2K token | 4K分辨率 | 4K token |
|---|---|---|---|---|---|---|---|---|
1:1 | 512x512 | 747 | 1024x1024 | 1120 | 2048x2048 | 1680 | 4096x4096 | 2520 |
1:4 | 256x1024 | 747 | 512x2048 | 1120 | 1024x4096 | 1680 | 2048x8192 | 2520 |
1:8 | 192x1536 | 747 | 384x3072 | 1120 | 768x6144 | 1680 | 1536x12288 | 2520 |
2:3 | 424x632 | 747 | 848x1264 | 1120 | 1696x2528 | 1680 | 3392x5056 | 2520 |
3:2 | 632x424 | 747 | 1264x848 | 1120 | 2528x1696 | 1680 | 5056x3392 | 2520 |
3:4 | 448x600 | 747 | 896x1200 | 1120 | 1792x2400 | 1680 | 3584x4800 | 2520 |
4:1 | 1024x256 | 747 | 2048x512 | 1120 | 4096x1024 | 1680 | 8192x2048 | 2520 |
4:3 | 600x448 | 747 | 1200x896 | 1120 | 2400x1792 | 1680 | 4800x3584 | 2520 |
4:5 | 464x576 | 747 | 928x1152 | 1120 | 1856x2304 | 1680 | 3712x4608 | 2520 |
5:4 | 576x464 | 747 | 1152x928 | 1120 | 2304x1856 | 1680 | 4608x3712 | 2520 |
8:1 | 1536x192 | 747 | 3072x384 | 1120 | 6144x768 | 1680 | 12288x1536 | 2520 |
9:16 | 384x688 | 747 | 768x1376 | 1120 | 1536x2752 | 1680 | 3072x5504 | 2520 |
16:9 | 688x384 | 747 | 1376x768 | 1120 | 2752x1536 | 1680 | 5504x3072 | 2520 |
21:9 | 792x168 | 747 | 1584x672 | 1120 | 3168x1344 | 1680 | 6336x2688 | 2520 |
纵横比 | 1K分辨率 | 1K token | 2K分辨率 | 2K token | 4K分辨率 | 4K token |
|---|---|---|---|---|---|---|
1:1 | 1024x1024 | 1120 | 2048x2048 | 1120 | 4096x4096 | 2000 |
2:3 | 848x1264 | 1120 | 1696x2528 | 1120 | 3392x5056 | 2000 |
3:2 | 1264x848 | 1120 | 2528x1696 | 1120 | 5056x3392 | 2000 |
3:4 | 896x1200 | 1120 | 1792x2400 | 1120 | 3584x4800 | 2000 |
4:3 | 1200x896 | 1120 | 2400x1792 | 1120 | 4800x3584 | 2000 |
4:5 | 928x1152 | 1120 | 1856x2304 | 1120 | 3712x4608 | 2000 |
5:4 | 1152x928 | 1120 | 2304x1856 | 1120 | 4608x3712 | 2000 |
9:16 | 768x1376 | 1120 | 1536x2752 | 1120 | 3072x5504 | 2000 |
16:9 | 1376x768 | 1120 | 2752x1536 | 1120 | 5504x3072 | 2000 |
21:9 | 1584x672 | 1120 | 3168x1344 | 1120 | 6336x2688 | 2000 |
纵横比 | 分辨率 | token |
|---|---|---|
1:1 | 1024x1024 | 1290 |
2:3 | 832x1248 | 1290 |
3:2 | 1248x832 | 1290 |
3:4 | 864x1184 | 1290 |
4:3 | 1184x864 | 1290 |
4:5 | 896x1152 | 1290 |
5:4 | 1152x896 | 1290 |
9:16 | 768x1344 | 1290 |
16:9 | 1344x768 | 1290 |
21:9 | 1536x672 | 1290 |
何时使用 Imagen #
Imagen 已关闭,无法再通过 Gemini API 使用。使用 Nano Banana 进行图像生成和编辑。